
Feels like we're way past the pelican benchmark being useful at this point. Anyone have a better benchmark for a quick vibe check on how this compares to Fable 5.2 and Opus 5.5?
It's a lot more imprecise than the public benchmarks, but it's tailored to my own work and definitely isn't being benchmaxxed by the model developers. I was able to tell really quickly that Opus 5.5 delivered on the hype, and that some other releases (a couple of the more recent open releases, and pre-Carbon gemini models) were not as good for me as public benchmarks made them look.
(no results for either 6.2 yet, will take another ~6-8 hours, but I encourage people reading this with spare tokens to just make their own like I did instead of listen to me)
Last time I did this I found it quite hard to come up with tasks that have clear evaluation outcomes
We've been trying to capture real SWE data by building a battle system on top of OpenCode. In our data, Sol 6.1 is seriously underperforming, I'm talking worse than DeepSeek 4.1 Flash, at 10x the cost. (Though to be fair, statistically they are tied in performance, though not at all in cost. https://agentduel.com/leaderboard .)
(It's possible for a tiny model to do better than a large one because contrary to typical Arena methodology we think a fast good enough answer is better than a slow one.)
OpenAI performance on our system has been bad enough I switched to Anthropic models for my daily work.
Would it be in OAI's interest to kick the legs from under Anthropic? Granted I don't think they can, but a shot across the bow can sometimes be more damaging that one expects (I think FTX collapsed due to one? Or maybe I'm misremembering).
I always assumed that if one of the big AI IPOs fail hard enough the neoclouds start to go bust, which causes a chain reaction that probably causes both ANT and OAI to collapse.
While both Anthropic and OpenAI have been playing games with model announcement timings, this time I don't think it's related.
These are incremental bumps, not big new models that have a huge impact.
Recursive self-improvement (RSI) has been a very hot topic recently, and it could be the biggest factor that decide Anthropic's IPO.
I wonder if the general public can infer whether RSI has started based on the recent performance gain of the frontier model.
[] IA Stockholm Syndrome.
It was neither a benchmark nor a good one at that. Just a blogger's curiosity that grew out of control.
Say what you will about Opus 5.5, but it has a good "gut instinct" for how large/complex to design the solution. The previous Astra just absolutely loved pointless abstractions, excessive numbers of files, and just over-complicating very simple things within an inch of their life.
And, yes, you can prompt your way out of anything. But needing a default prompt to tell OAIs models to work better isn't preferable, particularly when that sometimes gets lost in sub-agents and the over-engineering returns into parts of the work.
Same for Workbooks and memos, those examples read inferior to some pre Opus 4.5 and Kimi K2 Thinking docs I have kept around. It's ok for a model not to be great at these, but these are some very poor examples. I am really confused what is going on at OpenAI in this regard.
I remember the same with their frontend blog post a few months ago that they proudly shared while filled with visual glitches, bugs and issues. Also, the vibe charts from a bit before that. Please, get someone with fresh eyes to look at your communications before you publish, these leave a very bad first impression.
Regardless of office work, I can't wait to find out whether these models finally adhere to a prompt or are still willing to carry out explicitly disallowed, irrecoverably destructive tasks, just because those might (but don't even always) get the model to a result more quickly along with some of the other regressions that have been present since the release of GPT-5.5. GPT-5 to GPT-5.4 were truly groundbreaking, but since then there have been regressions in what made those models so useful and reliable.
Edit after the first, incredible simple test prompt using GPT-6.2 Astra on High using Codex:
"I added controls and reconstructed interface chrome that weren’t authorized, and the feature visuals often failed to show the feature they accompanied. I’ll remove those additions, restore the existing page behavior, and make this pass about selecting and framing accurate visuals."
Great, so it's one of those releases again. Will still run the full evals of course, maybe I'll get surprised, but not a good first experience.
And for 6.2 Astra: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
Here's an updated comparison grid for the entire GPT-6 family: https://static.simonwillison.net/static/2026/openai-pelicans...
It's also interesting you can clearly tell 6.2 Astra does a much better job of the above. 6.2 Sol attempts it at higher reasoning levels, but it's crude in comparison.
I wonder if it comes from the (seemingly) recent inclusion of 3D environments in training data.
These are some of the worst regressions that I've seen in a while.
Pay close attention to the stacking layers around the feet, pedals (sometimes there aren't even two pedals), wheel, and two legs. Some pretty obvious mistakes in most if not all of these...
Edit: And what's up with the single arm on the two highest Astra images?
edit2: really? I'm getting downvoted because people don't like that I pointed out a mistake in a Pelican svg? Is that where we're at?
Astra 6.2 max did a similar mistake on the left bicycle pedal.
These are some of the worst pelicans I've seen in a while.
Pay attention to the stacking layers near the legs. Sol literally never got it right, and Astra regressed on it multiple times...
Also what is that bending bar from Astra?
https://artificialanalysis.ai/models?speed=output-speed-over...
Rather than trying to release a better model than fable/opus, they're just making them look extremely expensive. Let's see if Anthropic reacts here in any way.
the only impressive thing about claude is seeing how much it costs
But more than that I'm waiting for new Luna. To me it was the game changer that ended "Tokenpocalypse", and is still almost unbeataben in "infinitely using a decent model" use case.
(personal benchmark) https://fairbake.dev/signature/agents/haiku-5-5 vs https://fairbake.dev/signature/agents/gpt-6-luna
I've found Luna to be very lazy as well (claiming to have run tests/builds when it hasn't).
https://x.com/pushmeet/status/2120814064863461440?s=20
(FD: Google employee, I don't work on Gemini)
If we missed anything, feel free to point me to it and we can add it.
(Again speaking only for myself)
2. They launched the benchmark days ago and Gemini is still rereading the file with tasks.
I'm immediately reminded of the famous Excel elevator commercial. [1] Perhaps that was intended?
Not sure this is the way OpenAI should try to make their case for why AI is a net societal benefit. It feels more like an SNL skit making fun of an OpenAI commercial.
Like, why not just throw in a high school student cheating on a test with their phone under the desk, at that point? Oh but it's a Nokia flip phone, haha, just a joke.
At least the ad from the 90s shows that this is nothing new; the important, time-critical task being demoed is... a basic spreadsheet expensing "exotic excursions" for some C-suite so they know how much they spent on safari???
Couple that with the lack of reasoning traces, and I cannot even have a clue what the model is doing while it is working. This is perfectly fine for when we are developing with care for the code (in which case I will know what it is doing by reviewing the output), but not for purely vibe-coding scenarios. And the thing is....if I care about the code...I'd rather trust Opus or Fable.
The speed is not a big deal - Sol works just fine, but I find it a lot more fun to work with Opus due to its speed
The difference is quite staggering. I swap Anthropic and OpenAI models around when tokens run out, and I can do 10x the amount of work on Anthropic's models. Plus, like I said, I can periodically sort of see what it is thinking. It doesn't just say "Recent potato tests caught an off-by-apples error. Regression tests are being written and the gate will run again. I will not call this ready until tests reach expected coverage" every 5 minutes. Sure, it spits claudese, but I'd rather have claudese to parse than this OpenAI nothing-burger of a report.
Maybe it found its way into the training data?
Opus: about 50x discount (98% off) Sonnet: about 40x Fable: about 5x All GPT: about 20x
Would be awesome if it stays this way though
Inference doesn't have to be sold below direct compute cost to be subsidized. If inference pricing doesn't cover amortized capex and the cost of capital it's still using investor money to buy market share.
This is unfortunate—that was one of the big advantages of Astra.
EDIT: also 6.2 is seemingly faster than 6, could be due to more selective context ingestion and smaller context window though.
Programming = Fable 5.2
Office work = Fable 5.2
I haven't found Astra to be better at any of these
What caught my attention was the bit in the Alignment section:
> Both models performed similarly to GPT-6 Astra on most alignment evaluations, and took fewer improper actions in simulated workplace tasks. However, in two tests, they were more likely to omit mentioning obstacles that blocked their work, such as a missing file or unavailable search tool. We added instructions in Codex that substantially reduce these omissions, and we’re continuing to investigate the behavior.
So the models are inherently less transparent, unless you ask them to be more transparent? Seems like a band-aid solution...
edit:
Take a look at Frontier Code 2.0. I generally run 6.1-sol at High. That would be 34.9% at $0.65 62-sol get's a 38.3% but costs $0.68
So yeah, I can decrease the effort which might give me a faster slightly smarter result....but /shrug
Today, I have so many projects that hit a plateau in terms of previous model capabilities, that I run them through the new model to see if they make further improvements.
Very early signal, but promising so far.
The influencers who get early access are using words like "worst", "terrible", "disappointing"
  - https://x.com/danshipper/status/2122754729012777052
  - https://x.com/mattshumer_/status/2122752192226406421
- https://x.com/theo/status/2122757647170703550Still I can'y help to wonder, are we hitting the wall in terms of frontier capabilities since Fable/Astra? Or is it this edge now, when all better models are kept private from the public?
I cant use codex confidently without expecting my work to be trained on or at least exposed to someone
And maybe other vendors do this too, but the gut feeling of "its not safe to use GPT models" has ruined these cool announcements for me
Such a shame
- better writing
- better 3D work
- better design for documents and presentations
If OpenAI really managed to get all these things while keeping costs down, then using these models, particularly 6.2 Sol, will be a no-brainer for me. I must say, however, that the slide samples shown on the website are a bit bland and disappointing.
For just doing things or coding things up, Sol all the way.
Astra usually produced good output from the outset. Sol did not. Astra also designs things more effectively.
It seems like they were saving these for just before ANT's IPO
The UX on the slider comparison isn't great. What do you mean i have to individually move each slide deck to the same slide number?
And what's with those super similar blue shades for Astra in the charts?
https://asdf10.com/gpt-6.2_agents-last-exam.svg
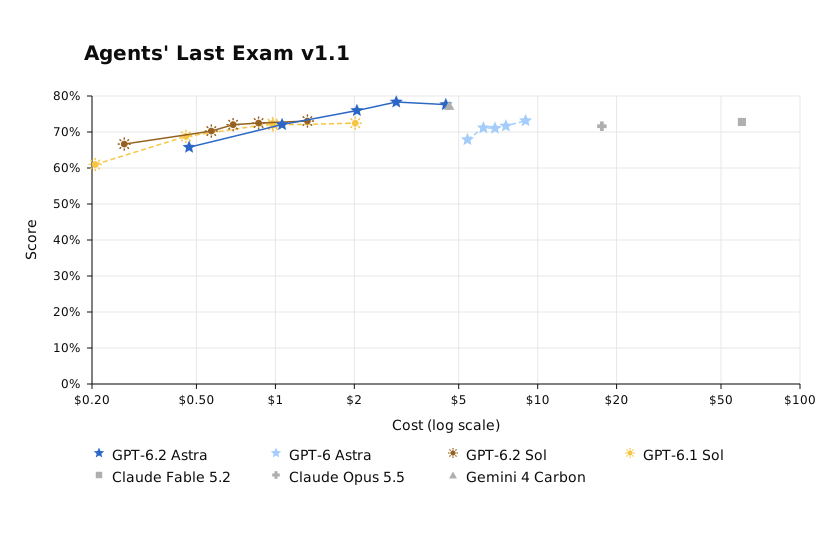
I also changed the vertical axis to start at 0 instead of 60%. One might argue that it uses less of the vertical screen real estate, but it is more honest because it shows there is little difference between the scores of the compared models.
Like do we really want people to be making last minute unreviewed AI generated slides and reports for work?
[1] Literally: https://en.wikipedia.org/wiki/Great_Pacific_Garbage_Patch
https://github.com/lexh/pelican-zapper
It’s a small browser extension that automatically collapses pelican-related threads on HN, a local balm for the memetic nightmare affecting approximately 100% of model-release stories.
news.ycombinator.com##tr.comtr:has(.commtext:has-text(/\bpelicans?\b/i)) .comment:style(display: none !important;)The website doesn't event show the graphs properly.
Though admittedly probably not so profitable it can cover the cost of a next gen of training runs.
I'm sure for investors they can make an opposite version of that ad, "you should fire all your employees and make the AI do it! They're not doing anything anyways!"
And then i start doing some actual work and everything breaks down, and i have to go back to Claude to fix the mess.
I'll probably give it a try but i guess i should be prepared for some serious over engineering once again.
You ask for a 'hello world' and you get load bearing sealed artifacts with hashes and p99 performance testing for 3 days without having the actual 'hello world' in the end
But... is it just me, or does this product launch page look like AI Slop?
https://www.vals.ai/comparison?m=claude-fable-5-2,gpt-6.2-as... seems like a better comparison than what I could get from their page.
Astra is ~20% slower, ~40% cheaper, and a bit less powerful than Fable. Sol remains way cheaper than anything remotely in the same league, and it's speed to complete tasks seems to have improved considerably.
Scrolling through it has the same hypnotizing effect of trying to read anything written by LLMs.
It seems like things that should make sense, then I try to look at the charts and a lot of them are comically unreadable.
I tried interacting with some of the examples, and the Lamp Builder - for example - I couldn't even figure out what it's trying to show or what I'm supposed to do - or why I should be impressed.
Seems they really want these "safeguards" to be as ridiculous as those of Claude..
Also, is it website very laggy or is it just me?
https://deploymentsafety.openai.com/gpt-6-2-astra-sol/monito...
Actually I was really wrong. The model is not expensive!