
If it's based on carbon-14 it will lose half its model weights in 5,730 years; if it's based on carbon-12, it's a stable release.
In all seriousness, if Google must continue gambling on pre-train runs, at least have a useful naming scheme. Like the month it was post-trained and the parameter count. At least that’d provide some insight.
Gemini 2T 10/26, bit of a mouthful but is it truly that much worse?
But I come from a latin language background, so maybe I'm a bit biased there.
Size wise Astra is not categorically bigger than Sol, both in absolute terms and the observed size.
The naming makes perfect sense to me, the sorting algorithm is size, both for the names and for the models themselves. Smaller things represent smaller models, and vice versa.
I would need to be a complete moron to argue with this. Humor me, however. My Latin skills end at remembering "Romani Ite Domum" and English is not my first language.
My layman reading of the names: there is one Terra, one Luna and one Sol => "Astra" is singular.
Now that I googled it, I understand that "Astra" literally means the "Stars" category. I would not have thought that they called a single star "Astrum". On the other hand, I am not sure if it means "Galaxy" in modern sense, but we're entering Roman Astronomy territory, where I am even less knowledgeable than in the language.
Sol is a star, so having a dedicated Stars category on the naming scale makes less sense. Treating Astra as Stars set without Sol, the "distance from observer" argument still kind of makes sense.
That is incorrect. "Astra" is Latin for "stars" (plural). The singular would be "astrum".
    Luna  = Moon
    Terra = Earth
    Sol   = Sun
Astra = GalaxyLeopard (10.5) and Yosemite (10.10) both came with clear version numbers
Model X and Model Y are siblings which do not have a clear hierarchical relationship
Gemini 4 Carbon and Gemini 4 Argon are rather difficult for me to tell at a glance
Same for Anthropic, consistent model tier naming reused across model generations.
Those are just like i3/i5/i7 or M-series Pro/Max/Ultra.
But Carbon seems to be full replacement of Argon announced two weeks ago, they're same price. So Argon doesn't mean anything, they just picked random element.
They'd be fine except every named model has multiple numbered versions, with no consistent relatioship between cost or capability corresponding to the version numbers going up or down.
He's always been deeply unserious.
The pedo-guy comment though I think was him being serious, unfortunately.
  O, B, Sc, U, Re?
Ra, Nd?or I'm dumb and its just elements with names starting with A, B, C
I suppose a Fable is seen as larger. But some of them can be quite short, and not generally considered poetry.
Maybe it thought the names are clear and intuitive (for an LLM perhaps).
There are no good elements for D; Dysprosium is the only one, and it's a mouthful. There are no good elements for E; Europium is the only one and would seem political. Is Fluorine their next release? (And then Gallium or Gadolinium?)
After Carbon, they should just update to Gemini 4.1 or 4.5 or whatever, and drop the random unrelated elements.
Its sad watching them try to keep up when they want nothing more than to crumble under the weight of their own bureaucracy, and at this point I'm not sure there's any hope for them.
I needed batch mode. Oh but the key from service X doesn't support batch mode, you need to go service Y and btw there is no UI for that so you need to use an SDK or API (cant even remember anymore). Spend an hour figuring that out, then it turns out I can't use batch mode because I don't have permissions. Have boss spend an hour granting me permissions. Then service is unavailable every n requests for 5 minutes, so I have fuck with exponential back offs.
Glad to see they moved that experience to their consumer offerings lol.
* 3.5 Flash-Lite
* 3.8 Flash
* 3.1 Pro
* 4 Argon - New
And honestly, the versions are hurting their case. I ask myself “how is the oldest model, the Pro model?”
This kind of bungled naming and versioning is the kind of thing I expect from Microsoft.
I noticed the usage on chat is absymal, but it could very well be that their own harness does a good job in caching and you can squeeze good usage out of it due to this.
I'm fairly confident I can't call Carbon, and I am okay with that.
It is the most awful product experience I’ve had this year. How could they fuck it up this badly?
wow pricing has gone way up
Now, I just go straight to the Hacker News comments. I've given up on trying to figure out how to navigate Google's labyrinth.
Their release notes have become like breakthroughs in graphene. I'll believe it when I see it.
Their go-to-market execution is just so broken.
At the beginning of this whole AI shift, when Google would announce a new model, I would try to get access, even paying for a subscription.
Then I realized it's just not possible.
Google onboarding is the new Gordian knot.
For Google, I think the announcement is the success criteria. And onboarding is somebody else's problem. And the problem is... that somebody doesn't work at Google, or are entirely disempowered.
If, someday, Hacker News comments indicate that a majority of individuals have figured out how to access these newly announced models consistently, I might take my precious personal time to navigate the labyrinth once more.
1. Ultra - The best and the most expensive for showing off and government. 2. Pro - Almost best but substantially cheaper for most productive people. 3. Flash - Workhorse for everyone. 4. Lite - For the unwashed masses and peasants.
There is no need to attach anything to these labels. In fact industry could simply standardize these namings like SEMVER.
There could be an internal representation which could give specific number of the model but these companies should move on to be more like Chrome. No one knows or cares which version of chrome they are on.
For a lot of systems the real underlying version would matter because of reliability. That can be provided to those power users.
honestly, this tier is the 4GB model that ships in chrome and runs locally
Not if you're a linguistic descriptivist.
As an example, Linux distros say, Ubuntu got its project "names" as well as SEMVERs. But people rarely use project names but uses versions.
You tell me, I use "Jammy Jellyfish". I will be like WTF dood. You tell me 22.04 LT (which is one I use), oh yeah, that's a good one.
Same thing here. companies can call whatever SOTA whatever they want. But in the end people will refer to them as just Gemini 4 or Ultr/Pro/Lite however people like to use.
Just leave it to company's discretion. Don't enforce anything. People will figure out how to call it.
---
And wtf, a peaseant?
I use your so-stupidly-called ultra/med/lite but in diff situations, and when I use lite that doesn't mean I am peasant, I am being sensible
Has there ever been a product category where a product release is valuable for a shorter time than with LLMs? Trying to build SOTA models seems like it'd be an exhausting hamster wheel to work on.
Just. Yaknow. 100x the costs, at the least.
To be honest, if I were an LLM provider I would be wiring up my release process to be fully automated so within 10 mins of the last bit of fine-tuning it got released and a blog post posted.
Also the whole "we're only releasing it to cyber defenders first" framing is weird, is any Gemini model an actual cyber risk?
Just because you saw your friend move to a new country for a job doesnt mean you will make the same choices, even if you are similarly qualified.
Seems like Google could do it too.
Anthropic and OpenAI are not releasing their best models for several months, because their second best models are still better than everything else available.
I suspect they're announcing it for two reasons: to get ahead of all the leaks; and because it's earnings report day.
Especially on their Plus tier for Gemini.
I think it's a fair concern that this might take weeks and trail Fable 5.5.
The Google AI Plus tier does not give better model access than free, it is strictly for usage limits. Same thing as ChatGPT Go (which currently only has access to GPT-5.6 Luna, same as the free tier too.)
[1] For consumers at least. IIRC google business/entreprise accounts have worse model access even in the business/entreprise version of Google AI Pro.
Google has the products, the brand recognition, the hardware, the data and most importantly a billion normies.
Google was always going to win this thing, although I wouldn't discount meta. The only thing that matters is mindshare and Anthropic and OpenAI have largely generated NEGATIVE sentiment, outside some fanboys.
Google and Meta can plop cute products into your daily driver apps and you wont know the difference.
Google’s talent is solid B tier in 2026. Better than IBM but worse than Microsoft and Amazon.
Even if Google had “talent” this talent wouldn’t be able to accomplish anything due to corporate politics.
Anthropics only moat is vendor lock on Claude Code, especially if they cant maintain being the front runner of the frontier model space, this is a really brittle moat. Brittle moats wont attract strong investment at a 1-2T valuation (not to mention all the other fiscal unknowns).
I just want OpenAI and Anthropic to lose because they seem to be the ones going around saying they're going to replace peoples jobs, and usurp the value of human labor.
Id rather Meta and Gemini suceed who will genuinely just integrate it into normal products we already use. Their sales teams are not approaching my boss and telling them they can reduce their payroll burden by spending my paycheck on tokens and firing me.
Coding is going to be one of the smaller pieces of the AI revolution. People on this site are focused on it, but there are 10000x more opportunities outside of coding where Anthropic and OpenAI have zero presence. Anthropic might as well be an IDE company, Is jetbrains worth 2T? to signal that they can be useful in other fields because they know this is an issue.
I don't see why an alternative provider that is quiet but also scrambling to make AI smarter is any safer for jobs. Wouldn't we rather orgs speak honestly about the risks of the industry?
I find it odd that we talked for decades about companies being evil for covering up problems (chemical companies, etc), yet it turns out people hate the ones that talk about risks openly even more.
Outside their most successful products (YouTube, Android, GMail, Chrome, Search), their products are usually worse than their competitors (e.g. GMeet vs Zoom)
> the brand recognition
Of not maintaining/outright abandoning their products, and making Search worse over the years?
> most importantly a billion normies
ChatGPT has 1.2B weekly active users, all the normies know what ChatGPT is but don't know about Gemini (outside the "AI Mode" stuff)
I dunno if that's a great example - I'm sure Zoom has more awareness in the zeitgeist, but from my standpoint it's an app most well-known for security problems and abusing OS conventions, while Google Meet just quietly and simply works whenever I want to call my mom.
They have many successful products. Most have only 1-2.
Youtube, Android, Chrome, Search, Photos, Workspaces, Cloud, Fitbit, Pixel Phones, Waymo not to mention dozens of open source projects.
> Of not maintaining/outright abandoning their products, and making Search worse over the years?
You just said their products are terrible. They do shut the products that do not meet the bar. That is good thing.
> ChatGPT has 1.2B weekly active users, all the normies know what ChatGPT is but don't know about Gemini (outside the "AI Mod
No one needs to know what Gemini are. If they have used search they have used it.

[0] Practical Data (https://practicaldata.dev/ / https://chromewebstore.google.com/detail/practical-data/oeoo...)
https://files.catbox.moe/2aqfk7.webp
(Edit: For some reason the previous jpeg link: https://files.catbox.moe/yjqa0a.jpeg wasn't working and catbox.moe was just downloading 4kb white screen so I converted the image to webp and reuploaded it on catbox)

Anyway, Imgur creates so many problems that it should be retired.
Opus 5.5 in comparison is a bit more verbose and appears to settle on evaluations before the depth reached by Fable on very complex stuff, but is still vastly capable and I can read its output without wishing it had a physical form I could punch in the face.
It's possible Fable is better, but since it word salads more quickly, it's hard to tell.
I generally use Fable for high-level blueprinting, architecture, and technical planning, and I tell it to write most of its documentation in a way Opus 5.5 will understand and maximally benefit from; with the added prompt for Opus to concede when a task would be better off to bring Fable back in. I've had ZERO problems.
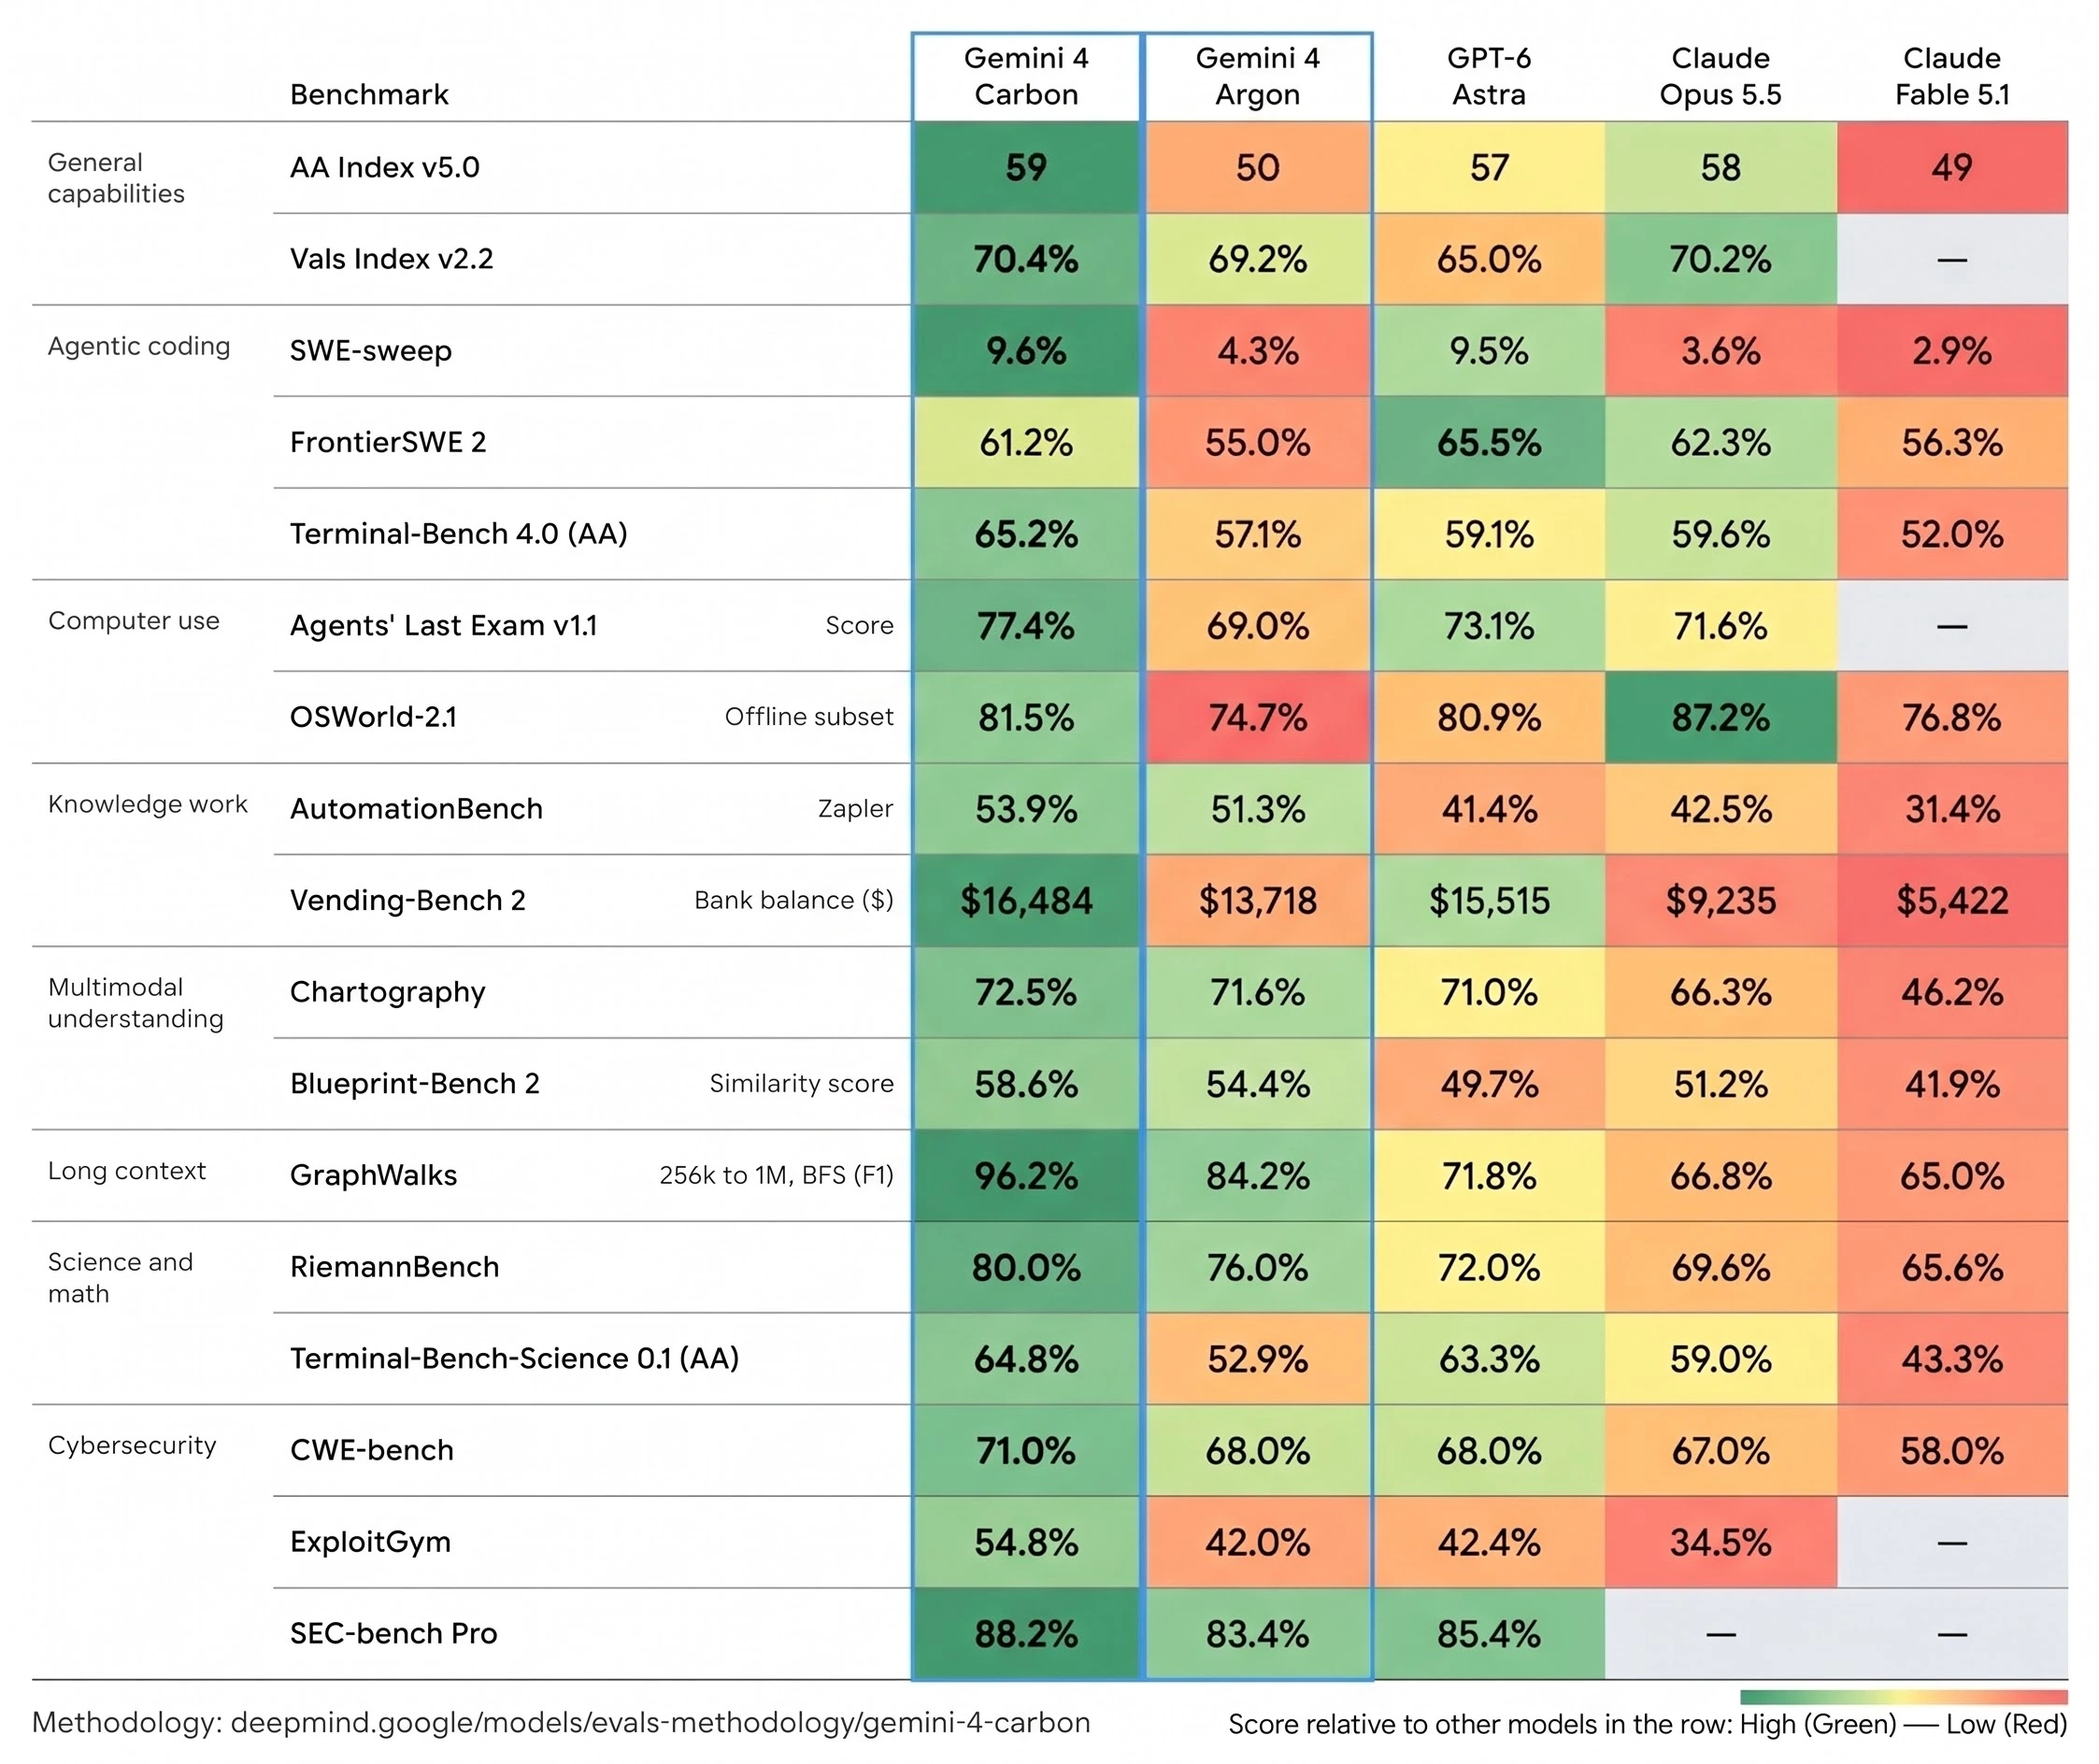
On the other hand I'm a strong protan colorblind guy (red doesn't register to me very well at all).
https://file.garden/auI5UdLIWwZSu5X8/pilestone.png - result of said simulation.

Also, I'm curious if you just asked an AI to _OCR the original image+update it_, or if you used a different process?
> "Edit this image to color code the benchmarks scores using a gradient scheme that is immediately obvious"
It's worth trying if you have easy access to it (we use Cursor at work, so it was just a matter of picking a different model for me). Don't know if I'd go out of my way to get a Google AI subscription for it, but if Carbon ends up meeting these expectations, then it may be worth doing so.
It's best to start with a relatively clean GEMINI.md too. Many configs optimized for Claude doesn't work well because Argon didn't have those same failure modes.
It's sad to see Carbon releasing at the same pricing because that implies Google is planning to do the thing everyone is doing: release promising model for subjective preference, RL-maxx a V2, replace promising V1 with V2 because it benchmarks better
Muse did it, Kimi did it, Deepseek did it, Tencent did it. No one seems to care abojt subjective preference anymore.
Top is Opus 5.5, followed by Fable.
  - Corrupted/dropped Gemini thought_signature (reasoning_details) in tool loops
  - Blinded model.api.id = "contestant" bypasses gemini.txt and serves Claude's prompt (default.txt)
  - Anthropic-only prompt caching
Prompt was:
> I read on hacker news the following, which does not match my expectations. Check if something in the harness or bench is hurting gemini perf.
followed by your post.
> anthropic only prompt caching
Anthropic has custom prompt cache requirements, but we've verified all providers are working well.
> Blinded model.api.id = "contestant" bypasses gemini.txt and serves Claude's prompt (default.txt)
This is wrong. We're serving default.txt which is opencode's default prompt. We are not serving a custom prompt for any model, including Gemini.
> Corrupted/dropped Gemini thought_signature (reasoning_details) in tool loops
We blind the reasoning details in the frontend because this would leak information. Some models summarize thinking while others provide raw thinking. I'll check if we're corrupting the thought signature that's actually sent to the backend.
So far this sort of looks like an example of Gemini being bad. Was this Argon?
Their agents leaderboard is literally just randomizing the agent and looking at metadata like tool call errors. In my opinion, it's poor quality data in high volume.
Their web dev leaderboard is in cloud containers, most people don't run agents like that.
I ran a statistical test on our data. Deepseek vs. Argon. Posterior probability DeepSeek 4.1 Flash is stronger: 99.1%.
It's possible, but we are getting real prompts from people on real projects, and the instructions about the battle are pretty minimal.
Argon in low and medium mode had higher quality results than it did when running in high mode, almost every time. My tasks involved the agent finding some details in a raster image and then mark it up with predictions about what it found.
Argon on high would do the work, and then a whole bunch of other stuff i did not ask for. All that extra broke everything else downstream from the analysis.
However, doing the same work with Argon in low effort was on par with results from Haiku 5.5 (xhigh) and GPT-6.1-Terra (medium). So, Argon low works better than Argon high, but for my tasks -- a very weak model relative to how google positions it.
I'm ready for Geimini Unobtanium!
what does "local" coding agents mean? Surely you're not hosting it..
But yes, Opus is a tier above Wonder and Argon with very high confidence.
This might be the first comment I've ever seen saying something nice about the model.
For me it also works the opposite way, when it actually comes out eventually it’ll already be old news.
Having said that, I don't see people excited about using Argon so far, so that might be why Google is announcing this to hype Gemini up a bit.
Anthropic has been doing this with Mythos for quite some time...
I don't understand why HN is so surprised to have an announcement for model existence and a follow-up announcement for model availability. It's really not that unusual, as you say Anthropic has done the same, probably others too (though I can't remember)
it actually did really well.
But it still annoys me: I told it to _tell_ me something, and instead it _implemented_ the something. The previous models were way too eager to just jump in and do and this one seems no different. But the optimization it identified was both really solid and just a good engineering choice, and better than what Opus had been suggesting.
It also gave pretty good feedback on a bit of writing.
Consequently, I have zero intention of renewing my Gemini subscription. What a dumb business choice they made.
Updates to your Google AI Plus plan
We wanted to let you know about changes to the models that you can access with your Google AI Plus plan.
Starting on 1 3 N o v e m b e r 2 0 2 6 , the ability to select Pro models in both the Gemini app and AI Mode in Google Search will only be available to Google AI Pro subscribers and above. You'll still have access to our latest Flash-Lite model and Flash, built for speed and intelligence. Your previous chats using the Pro model can be continued with a different model.
To learn more about these changes, you can visit our Help Centre article for additional details. You can manage or cancel your subscription at any time.
Thank you for being a Google AI Plus subscriber.
It has a seperate weekly limit that is very low. Maybe it can be pulled off that usage tier and just regular usage since Carbon is being released?
But it just all seems so tedious when codex and Claude are so painless.
Unfortunately their plan structure is on par with their model naming.
The plans that allow for own domain and the plans that allow for sane AI use are mutually exclusive
I bet I am not alone, either.
If you are talking about free versions, OpenAI and Anthropic also have a difference between free models and models available to 25$-tier plans.
Thanks for sharing your experience though, it's a more substantive piece of information than who I was replying to.
Doing this two hours before today's earnings report.
It's probably going to be a terrible earnings call in terms of capital expenditure, cash flow and new borrowing.
Now you know why they released it just before the earnings call.... :-D
This is probably the single most important thing to make frontier models usable right now, so I'm happy there seems to be some progress. This was the previous Gemini's biggest problem IMO
"We patched every vulnerability we knew". Meanwhile, prompt-injecting Argon (or any other model) is still trivial, and Carbon won't be an exception. Because the attacker is not limited to things Google has evaluated.
AI shops are blind to anything that's not a metric.
Is Argon "pro" and Carbon "ultra"?
Is Argon obsolete now? Does Carbon replace it or live alongside of it?
Very confusing naming!
Makes me think it's further post-training of the same model.
Or you might get Gemini 5 Arizona.
Argon is like Sonnet
I suspect they're using a new naming convention because they had previous contractual obligations tied to the "pro" and "flash" naming, and by switching to a new naming schema they avoid those commitments.
Does that mean Anthropic now has a copy of Google's source code?
[EDIT]: thanks to people in the know for their answers.
Follow-up question:
if Anthropic models run in a Google cage, does that not also mean Google can distill Anthropic models even easier (both fast and unseen)?
Anthropic is indeed trusting Google and other companies they rent compute from. Distilling or stealing the weights would be a contract violation, and would wreck other business relationships. I would be less worried about Google doing this, and more concerned if there is some sketchy neocloud in a van offering suspiciously low pricing.
Not really in the interest of the cloud org to allow that, they don't really care how well deepmind is doing as long as they can sell TPU and API (incl. reselling openai and anthropic).
I'm not going to comment on others use of Carbon except to say some article that came out before Argon's external launch saying Googlers hate it was nonsense. Not to say everyone loved it all the time.
I use Carbon heavily and am quite happy with it. For complex designs I may have it and Opus iterate back and forth on the design. They have their own strengths and Opus 5.5 is great, but I use Gemini far more than I do Opus at this point. I know a lot of the jagged edges of Gemini better than Opus though, so take that as you will.
3.8 Flash + /boost is very capable.
And do you have advice on how best to use Gemini models? It seems like my usual strategy of iterating on plan md file -> implement based on plan doesn't seem to work, 3.8 tends to rewrite the plan too often removing crucial parts when iterating.
deepmind should get rid of those antigravity ppl they're a joke and sabotaging the model's reputation.
Tried 4 Argon, and it's very much different from 3.1, felt very much the same as any other Frontier, just without the intelligence.
personally i like 4 Argon, it's very clever for me in a very different way comparing to the other two (especially via api) but when it comes to the google products.. sigh. nobody who's actually working on these products really cares about them in google now (maybe notebooklm is the rare exception), they're either not dogfooding themselves or somehow intentionally poisoning the experience on purpose, or simply inqualified. poor gemini is suffering in agy i can tell, it struggles so much and wont even use simple tools properly. if you put it in any good 3rd party harness out there it's flexing way better than agy and this tells a lot.
What harness are you using with Argon?
Is it a variant of Argon? A different model? The next version? It seems like this is a separate class (like Anthropic's Mythos).
anyway, its needlessly confusing.
What a coincidence it is!
[0] https://blog.google/innovation-and-ai/models-and-research/ge...
After all they had Nano Banana for years.
If all you want to prove is your internal models deserve a seat at the big boy table, maybe OpenAI and Anthropic should also release benchmarks for GPT 11 and Opus 9, launching in 2030.
https://www.ft.com/content/8158cb5a-4bbd-43fd-b329-15a54e842...
3.8 flash is a really solid "everyday" model. Was hoping a new flash model would be the next release.
But to be honest I am now not sure if Argon was the flash model and this Carbon is pro? It's very confusing.
So more capable and same price? I can at least appreciate that
    - 3.6 Flash
    - 3.8 Thinking
    - 3.1 Pro
Back I go to the Antigravity pricing page and there is a tier "For Organisations". But now I have the option of either contacting sales (are you kidding me?) or "Start now via the API".
So I'm out - I want a simple subscription like Claude or Codex. I don't want API enterprise pricing for a 2 person organisation. I could use my personal account but I'm already paying increased Google Workspace prices to access Gemini and I can't even use the latest models with that.
If someone at Google sees this, flag this ridiculous behaviour please and get things under control. It should be a very clear process - don't show me things I can't access. Price things consistently and please just make things logical.
Actually....looking in more depth I may have to upgrade to something stronger than "not my favorite benchmarking site". The first OAI model on there is GPT 5.4 at 31....that's not really credible.
Argon - 18
Boron - 5
Carbon - 6
I don't think I'll be able to cope with this level of elemental disorder.
I’d like to think other labs are making similar progress but hold their cards closer to their chests. Because it doesn’t seem that there’s much value signaling capability ahead of release unless you are “behind” in market capture.
Love the options but also I hope Google understands that they need to now compete on many dimensions for developers. Google probably will still win huge shares of the consumer market, though frontier intelligence will have little to do with it, other than the RSI aspect.
Both A and OAI regularly screw devs on quota. Switching for many is easy, you just run agy cli instead of claude/codex, and enjoy Ads free youtube and music + 20TB of google storage.
Whatever. Pass.
I dunno. The consumer Gemini shit is so infuriatingly bad. I have had Google home, tv, and pixel for many many years. The assistant product is so embarrassing for how much of a headstart they had. It's not like they don't have the talent.
Basically everyone[0] thought yesterday's update looked suspect, even before we knew about Carbon.
Did Google coordinate with AAI on any aspect of this in a non-public way? Is this the sort of thing a publicly-traded company would be obliged to disclose, if they were involved in it? AAI isn't a regulated company (private), but the stuff they print influences stock prices.
[0] https://news.ycombinator.com/item?id=50268868 ("Artificial Analysis Intelligence Index v5")
This has to be an intentional echoing of the "pace the frontier" language?
I tried to figure out if I could reproduce Carbon's aggregate score using yesterday's (v4.3.2's) benchmark weights—but apparently you can't actually do that, without paying AAI. The raw numbers going into that aggregate aren't available on their public website.
Next: Silver, then Iodine
Slowly spelling out ARC-AGI
Again, no access to open source developers. The AI companies want bugs for dramatic public relations! Also, of course there aren't enough bugs so they have to be rationed for the "defenders" and future models.
https://blog.google/innovation-and-ai/models-and-research/ge...
https://blog.google/innovation-and-ai/models-and-research/ge...
Does their Pro plan have similar limits to OAIs $100 business plan for example?
Any equivalent for the 20x plans?
Barium > Argon > Carbon
Why is carbon then more capable?
They cut down 1.5sq miles of man made logging forest that was rezoned to industrial land (and sold to google), without getting the right permit first, and it's been international news for almost a month. Anthropic and OAI are still small fish, at least publicly, so they can get away with far more. If Gemini was doing the shit OAI was doing with agent hacks and the like, there would be congressional hearings and $10B in european fines.
When you are a megacorp, perhaps here even the megacorp, every mistake you make is worth millions to someone, the government, the media, individuals, or all of them
I’ve heard from multiple labs that model release is up to the US government now.
You can also see this with Astra being announced and then launched a few days later.
I imagine they all want to avoid uninformed knee-jerk legislation, so preventing a "three mile island" type incident that would freak out society and congress would be common ground alignment between all the labs.
The air around AI is already dense, but it would suffocate the industry overnight if something like a large scale financial attack or grid attack took place.
I don't buy it.
SpaceX is not exactly a small corporation, and they nevertheless strike me as far less risk-averse than GOOG and they deal with actual hardware that actually effing explodes.
This isn't about a "slip up", it's the modus operandi for Google since it was young. Press releases instead of real releases. I can't count the number of times I've clicked on a "launch" story from Google on HN only to end up on a blog post with an embedded youtube video, and nothing else. Google just doesn't get it, and this is one of the many ways that manifests.
> man made logging forest
This isn't an old growth forest, these are trees planted specifically to be cut down.
Clearing the forest and failing to get the permit are two distinct events here. Google is in trouble for failing to get the permit. Not for clearing the trees. Everyone on both sides was aware the trees were coming down. Think of it like camping at a campsite without getting a permit first.
Failure to get a permit is non-news for almost every entity on Earth. Except when you are megacorp, hence my comment.
Corporations should not break the law, period. Weird that anyone would defend that.
The forest was put up specifically to be cut down. The default state for these trees was to be cut down.
If you can’t see the difference between this and clear cutting of something like an old growth forest, then there’s nothing left worth saying to you.
It makes no sense to need a permit to cut down logging forest (legally acquired private property) in the first place, so I'm wholly unbothered by Google's actions and don't believe they reflect a moral wrong.
There is limited public attention. Wasting it on such a minor infraction is unwise. Much better to focus on more egregious examples of corporate wrongdoing.
Anyone can promise the moon in the future.
If Google Cloud was in charge, Gemini 5 would be public, and they wouldn't be messing with Gemini 4 nor 1M context when they have 10M internal. C'est la vie.
I use DeepSeek too but it’s more of a workhorse model, requires a lot more guiding and sometimes struggles to get where I want it.
If you compare to "smart" from a year ago, you have endless options that are basically free at this point which outperform everything from a year ago.
Deepseek Flash V4.1, Sonnet 5.5, GPT6 Luna, etc are really strong for the cost.
“Helium” in Spanish is “Helio.” And Helios was the most powerful AI in the Deus Ex universe… Coincidence??
I thought it's not actually available to anyone? They announce huge challengers, but they don't exactly "push" them out...
How do you do fellow frontier models? </meme>
Excited to try it, opus level benchmarks with their omniscience score and multimodality seems worth testing!
https://artificialanalysis.ai/articles/artificial-analysis-i...
https://news.ycombinator.com/item?id=50268868
https://theainewsreport.com/2026-10-28-artificial-analysis-i...
IMO it emphasizes the wrong things if we are interested in "intelligence"
There are many more aspects which affect outcomes
Clicks link
Carbon isn't anywhere on the page and you can't toggle it on either. I'm sure it's just timing and it will be there soon but still just look amateur, which is about how I feel about Google and AI overall. I know the models have improved but I still have a bad taste in my mouth from testing Gemini in the past and I still feel that Google has an overly complicated "how to use our models" that changes way too often. That coupled with "you could lose access to your google account if we don't like what you do with Gemini" means I have little desire to test it out.
On top of all of that I'm completely over announcing a new model that we can't actually play with or try out. I don't think Google is lying about how well their model scored exactly but it still has big "my girlfriend goes to another school, you don't know her"-energy.
If you are going to hyperlink, maybe make sure that your model is actually on the page.
Also, the screen reader has a bug ([[duration]] minutes instead of the actual value) and you have once again announced a model we cannot use.
Edit: Both have been fixed after posting this. Maybe a Gemini 4 Carbon Agent has read and fixed the screen reader bug xD
I cannot fathom what motivates a lab, whose releases for the last year haven't been competitive, to shoot themselves in the foot like this. All this does is make it easier for competitors to snipe your actual launch, even if there was potential with this model (doubtful given 4 Argon, 3.1 Pro and 3 Pro), now everyone knows what exactly they need to release eval results wise to beat Carbon. There is this old idea of "Your competitor always is the first to have an idea what your next product will do", but in this case, Anthropic and co don't even need to guess, they got specific numbers to target.
Announce your models the moment they are available on API and in the subscription for all paying subscription users (cough Argon cough), stop with the cryptic tweets to drum up hype you know full well you won't live up to and make models that tool call, task adhere, task infer and handle long context tasks well beyond simple back-and-forth, chat style prompting. Reminder, during Ox Alpha, actual Google employees implied that was their model. How is this something anyone would believe is a good idea and how are they still allowed to tweet anything after? Please, stop that, it isn't helpful.
If frontier isn't your thing, stop wasting money on moonshot pre-train runs, fund research and open weight via Gemma and sell your inference hardware to other labs, that's far more lucrative anyway, as seen with Colossus 1.
[0] https://artificialanalysis.ai/evaluations/artificial-analysi...
Sort of? Yes, OpenAI has been bad about slow rolling but Anthropic's last few models have been available essentially at the same time as they announced it. In most cases I updated Claude Code and was using the new model right away.
Compare that to OpenAI who sometimes says "Available to all Plus/Pro/etc plans" without saying anything about "rolling out" and then it's a crap-shoot on when access will actually roll out. That said, they have gotten better, it used to be 1-3 weeks sometimes to get a new model/feature they announced was available for your plan.
And then there is Google... Who loves to talk about models like this and then give no timeline for release. Even when they do release the models it's miserable to find out how to even use it. Is it in the API? Which API? Google Cloud/Vertex/Gemini Cloud? Whatever it's called this week? Coding plan?
No, what Google does (or rather fails to do) in its rollouts does not compare to OpenAI/Anthropic.
As for the AA page, it's just embarrassing. Any smaller company doing that would get roasted, Google doesn't get a pass, learn how to coordinate or wait for something to actually be true/live before posting.
Gemini 4 Argon (at best Sonnet/Terra level) meanwhile took weeks to “come out” after their public announcement and when it finally did, paying Google AI plan users couldn't access Argon on Gemini or Antigravity even a week after. Three weeks from announcement to accessible for paying customers is not standard outside Google and this has been a problem with every Gemini release for the last year, so even using governmental requirements as an excuse isn’t possible here.
I will say that I dislike how OpenAI releases model only for Work and Codex but not via Chat, Anthropics "everywhere all at once" strategy is I feel the most user friendly.
Even in the optimistic case that this isn't some conspiracy, it highlights how arbitrary their scores are. I had trusted their previous ratings and their new index shows that even AA doesn't agree with them. What's to say this new index is any better and won't just change drastically again?
So if they are still vetting and changes can thus happen, that'd mean the score could change for better or worse. Not sure they'd want the embarrassment of a #1 score changing after announcement.
It's on my screen. Try asking your agent to refresh the page.
For historians, The blog post is 31 minutes ago so we can say that it was true for 20-30 minutes.
Slightly embarrasing but it seems to be the case that the model is actually worth what they were saying on AA. It's just that it is not available to people and I think that Anthropic and OAI will release a better model to public before google might.
AA has tons of its flaws too and the recent shift to their new v5 has been nothing but controversial for many.
It has better tuning towards not adding unhelpful caveats and irrelevant details. When I told it I was unhappy with some slop being dumped into some repo markdown files from Astra and Sol it actually went ahead and tastefully cleaned them up in line with how I expected them to be. Reductions are normally so bad from agents.
One big thing is that it really feels like talking to someone smarter than me. Other agents just seem extremely knowledgeable but Argon felt smart.
If they were able to make flash 3.8 so good off of their 3.1 pro model, flash 4 will probably be really good. But ofc you'd want your pro model to be as strong as possible in coding so that flash can take all those gains and efficient-ize them.
It's why Opus 5.5 is a beast
Any bad actor worth their salt is already a) going to have the weights downloaded, forever, to various models that are good at hacking and b) is out of reach of the U.S. government anyways. A ban on open weight models, plus paternalistic gatekeepers of cyber models like the big labs, just opens up Americans and American companies and municipalities to hacking from abroad. Or I guess to a really nice racket where only the big labs can offer a “we’ll continuously monitor and improve your cybersecurity for millions of dollars a year”.
“We're taking a deliberate approach to rollout and are actively engaged in the U.S. government’s voluntary process for pre-release model testing. Starting this week, we will make Carbon available to a subset of cyber defenders and will gradually phase access to additional trusted partners through our Fairwind Program. We’re continuing to gather feedback and iterate on guardrails before making Carbon available to developers, businesses, and consumers via our product surfaces as soon as possible.”
Obviously we want to be vetting the parties that get to use these weapons, because we want them to only be used as tools.
Mind you that Kimi in it's latest release nerfed cyber capabilities, as they stated. It doesn't make sense for China to be loose with this either.
I don't think I'm selfish, so that leaves me with naive or ignorant, I guess.
OpenAI: astral objects, bigger = better.
Anthropic: more pretentious = better.
Google: ¯\_(ツ)_/¯
But damn, is (talking about) releasing a new SOTA model two weeks after the previous one stupid. Do they not plan these things? Argon shouldn't be released at all if you're going to put out "argon 1.1" few weeks later.
What happens when all the good names are taken from the periodic table of elements?
I have registered calcium, helium, and californium for my California-based LLM.
Silicon Valley Clowns...
> [Header image is a chunk of ice]
???
When I mention a preference for brevity in a comment offhand and it snowballs into a rule 8 sessions down the road in a PR review that requests the removal of 90% of a colleague's docstrings.
I can't imagine all the "push back" on the "load bearing" Code of Conduct from their corporate foundation documents.
What's next Krypton?
you can definitely tell new people are in charge at deepmind based on the change in naming
Maybe I am just paranoid but at least if OAI or Anthropic ban my account I am not at the risk of losing access to my email address too.
You never know with Google and that is a problem.
Lol. The performance increase in the last 6 months has been massive.
I'm going to experiment with this one (assuming they ever get around to actually releasing it), and I'm really hoping the lame cultural aftertaste is gone.
Too bad you won't be able to use it to secure your open-source projects. If you try it'll throw up a prompt telling you to use some initiative you can't use or afford while the provider collects the findings. What a racket.
This post explicitly says that's been improved in Carbon. So, here's hoping. Google currently has the most generous usage limits on their $20 plan among US providers, so it's a pretty good deal.
Are you saying when you use Argon in antigravity it has generous token usage? I forget if I tried it with antigravity but my experience with using it as a chat bot was the usage limit was terrible.
The order of generosity, as it seems to be from my limited testing is currently Gemini->Claude->ChatGPT. (And, if we're including Chinese subscriptions, Kimi is below all of those. Very stingy.)
Come on googs!
With Anthropic and OpenAI, it's obvious immediately which are the better models. I.e. Sol is better than Luna, or Mythos is better than Fable.
But Google, let's pick Argon, which to most folks means mostly nothing. And then... Carbon! So which is better, Argon or Carbon? Nobody fucking knows. Plus neither sounds cool or viral or mysterious or even provokes curiosity.
When Fable was first leaked it sounded different and intriguing... Carbon just sounds... boring.
It is not obvious to me at all. I like Apple's naming more: iPhone Pro Max is better than iPhone Pro which is better than iPhone.
Sol vs Luna, how am I supposed to know which is better? Is sol a word, what does it mean? Same with mythos and fable. How am I supposed to keep track of these names across multiple companies? Why can't they use Claude vs. Claude Pro vs. Claude Pro Max?
The ordering seems to be based on size?
I actually like the google one. Alphabetical categories. Essentially alpha beta without the existing connation.
I think the bigger problem it’s getting harder to order models linearly. As later versions of the model make different tradeoffs across dimensions.
Mythos -> Fable -(sketchy)-> Opus -> Sonnet -> Haiku mostly checks out
Astra -> Sol -> Terra -> Luna checks out
Carbon ?? Argon
4 > 3.8 > 3.1 > 3.0
Unless you put Flash onto it, which denotes a lower cost version.
It seems like Carbon is a drop in replacement for Argon (same price). They can keep using random cutesey names as long as the version number + Flash naming scheme keeps making sense. Feels Android-y to me.
So no, OAI scheme is also confusing as hell. And they are going to add even more confusion when they release presumably Nova.
Oh yeah incredibly clear that a mythos is better than a fable /s
Mythos > Fable ? Opus > Sonnet > Haiku
Tho I think it’s definitely not obvious at first glance. And requires some thinking to order if you are even familiar with the terms in the first place (I had to look up opus)
That's fairly obvious to me. Most people associate Myth with the gods, which are kind of the biggest and most powerful things we can imagine.
Not so much of a stretch...
Wow. This huge. An AI company actually just said 'fabrication' instead of 'hallucination'. AI bubble about to burst...