
The slow warming of the water is a good approach. I’ve been using abliteration.ai’s cybersecurity models to pentest my own software and it produces much more usable defensive results. Opus 5.5 can fix everything but the guardrails trigger too easily.
The Fable ban affair was a nightmare for defensive cybersecurity. As far as I’m concerned we’re already in the world of Void Star and Cloudbreaker is here.
those models will follow your request when they already agreed to do this
deepseek tends to quickly assume this is benchmark and even when have web access thinks things like "simulated internet" etc (but waste tokens on thinking if there could be way to cheat)
Presumably they don't want you leaking your conversion transcript to a competitor.
This is the only AI-safe approach - see the OpenAI agent swarm incident where the swarm engaged in offensive cyber because guardrails were not active for their task and the model had clearly been post-trained on that narrow domain.
Deliberately keeping all models ignorant doesn't make sense. It won't work (whoever breaks the pact has a massive advantage); it won't be enforceable; it will have downstream impacts on things you don't want it to be ignorant about; this kind of regulatory regime invites adding more and more to the "no-no list".
Is it not possible to focus on hardening? And on new legal liabilities for operators who do security attacks?
I agree that it’s not obviously sustainable, but it’s better than specifically training these tools to be good at wreaking havoc, and then putting on a shocked pikachu face when they wreak havoc (ahem, Sam Altman).
Yet we keep completely unpunished offences that warrant arrests if committed by humans, and let them dictate who has access to what.
First, how much “cybersecurity data” is just standard software knowledge that one can derive cyber security exploits from?
Did they also get rid of all references to hacking in general?
Are they implying that all the recent exploits are just things that were already in the data?
For a model it doesn’t seem that far fetched to make the leap from “I have the knowledge of what hacking is” and “I know how computer systems work” to just being able to exploit stuff anyways.
For the models, it's always day one. They don't learn from experience. Whatever they know after training is all they'll ever know. So if you don't teach them penetration testing in training, they won't know it. Maybe they could theoretically derive everything from first principles, and so could a top 1% software engineer, but that's a very slow and inefficient way to do things.
Feeding enough source material as context can absolutely make them better.
Definitely going to give this one a skip.
You'd be surprised. Cyber offense is a very narrow domain, especially given the extensive mitigations that are being used in modern systems. Leaving it out of post-training tasks unless you're specifically interested in it is the no-brainer approach.
And then we'd also do that for all kinds of potential terrorism, sex-crimes, political subversion, and evil advocacy?
It would be the "restricted section" like in the Hogwarts library?
It's a really smart model but way too expensive. The same $20 goes 100x further with Claude. I used it for the initial task planning while the plan didn't expire, then handed off to DeepSeek or Minimax.
- OpenCode Go $10: I feel like most of the models are lower quality than directly from the provider. If you ignore my "vibes": the value is very good for e.g. DeepSeek 4.1 Flash (not sure if they're serving 1017 yet), GLM 5.3 Flash, Qwen3.8 Flash and Claude Haiku 5.5.
- Z.AI: Tried the $18/month plan and was disappointed by the usage limits. Even with GLM 5.3 Flash I ran into the 5h limit pretty quickly.
- OpenAI: I tried the $20 plan and $100 plan. $20 ran into 5h limits very quickly with anything other than Luna models. $100 felt like pretty good value for GPT 6.1 Sol, but as others frequently repeat: it's probably heavily subsidized and won't be around forever.
- DeepSeek API credits: I can let a single agent run all day (and not worry about keeping the context small) and am usually around $1 usage for the day. Flash 4.1 1017 is also a very good model IMO. For the stuff I've used it with it hasn't felt any worse than GPT 6.1 Sol. The benefit of API credits is also that they don't expire at the end of the month (like unused subscription usage).
- I haven't tried any of Anthropic's subs, but my guess is you can get a lot of Claude Haiku 5.5 usage out of the $20 plan which is definitely a good model. I'm just not a huge fan of Anthropic or Claude Code, so I haven't tried it.
Still burning through the 5-hour rate limit way too quickly, though. Output quality seems solid enough, but the value will probably make a lot more sense via API pricing for smaller projects.
My current tier list based on what I’ve been testing:
1. Opus 5.5
2. Astra
3. Argon
4. Kimi K3.1 Pro
(For lightweight/daily driver tasks, Gemini Flash 3.8, DeepSeek Flash, and Luna are still up there as favorites.)
Kimi K3.1 Pro ties Sonnet 5.5 at 93, for $0.68 and 11 min vs Sonnet's $1.61 and 14 min.
Kimi K3.1 Pro: https://jonclegg.github.io/pacman-bakeoff/#kimi-k3.1-pro
Claude Sonnet 5.5: https://jonclegg.github.io/pacman-bakeoff/#claude-sonnet-5-5
The prompt says that the agent shouldn’t look up existing implementations on the internet, so I’m guessing that the implementation is baked in?
That would have been interesting to watch, which model gets the highest score.
It's 55, at 4th overall, beating both GPT-6 Astra and Fable 5.1. It's also faster than both.
> When evaluating the Intelligence Index, it generated 150M tokens, which is very verbose in comparison to the median of 87M.
For example on programming, terminal tasks, troubleshooting etc Qwen3.8-Flash-Next is almost as good as opus 4.8. On "knowing what it doesn't know" it is far behind opus, but leads all other OS models I tested by a wide margin.
It out classes Glm5.3 flash and leaves models like DeepSeek 4.1 far in the dust. But you still get those silly aggregate benchmarks where GLM and DeepSeek are higher.
It is a small model, only 120B anyone that expects it to excel on general knowledge or to have a bajillion ready made workflows memorised is kidding themselves.
Everyone knows the bigger the model the better it will do on raw content of knowledge. But you know what compensates for lack of it? A good harness. But there is no compensating for lack of ability.
So in short I find all those aggregate benchmarks useless.
This is 100M fewer than Opus 5.5, 40M fewer than Fable 5.1, and about a third of Sonnet 5.5. In the top-6, it's 3rd, beaten by Muse Wonder at 140M and Astra at, impressively, just 60M.
Opus 5.5 high trails K3.1 by 1 point, but outputs only 53M tokens, so it indeed comes out cheaper per-task. I think it's still remarkable that this is effectively an open model that matches the frontier for the first time in a long time, pretty much since DeepSeek R1.
> reasonably priced when comparing to other models of similar price
???
Very similar to my adversarial programming language (KillSwitch) benchmark[1], at least on pass rate, it is much slower though.
From my own use of the models I find their ranking to be totally inaccurate.
The per token charts do not provide meaningful information for me
I also find the provider benchmarks fascinating: https://artificialanalysis.ai/models/deepseek-v4-1-flash-101...
I think lm-arena is a better concept that reflects the actual target users, but it only captures chat, and relies on users spending their time improving it.
I do trust epoch more than AA due to capital incentives, but in this case I don't think like there is a difference
It's fine if you don't trust them. You are free to put together your own benchmarks, run your own tests across models, and objectively compare results.
That's how you gathered your data to support your claim other benchmarks are totally inaccurate, right? Right?
So their base price is 1/5th of Opus 5.5 per token, but if you want "highspeed" it's 2x that and then I guess it generates 2x the number of tokens as well?
That might suggest that Opus is competitively priced after all.
But as noted by other replies, it's still lower than Opus/Sonnet.
Currently for today, it's 1.19T input tokens, 5.41B reasoning tokens, and 4.29B completion.
Therefore, reasoning + completion is 0.8% of the total usage. Actually below my estimate!
You can see in this discussions the goalposts being actively moved to desperately create a notion that the lead is still there.
You even see people in this thread referring to imaginary wonder models that they expect US companies to have under development that are supposedly leaps and bounds more impressive, albeit the only reference there is to their existence is the commenters hopes and dreams.
I think people need to realize that there is no longer a cutting edge company that is expected to dominate, and among the multitude of AI companies in the field competition is so tight that no one would even be surprised if tomorrow some other company far away from the US was able to crank out the top performing model, or something like a small local model that outperforms mid/high tier frontier models. The local model alone would be a death sentence to US companies, who are still burning through 10x their revenue.
It’s incredible how little GPU compute they have to work with compared to the US frontier labs.
Two years ago, tool calling was always considered an extra feature on top that some models where good at while other models completely ignored tool calling.
Meanwhile the discourse about how intelligent these models have become and how this is a major step or shift in model intelligence would make you believe that these models suddenly have a more powerful architecture when in practice model optimization has lead to faster but less expressive models that are still more intelligent, meaning that the model architectures didn't really experience meaningful shifts, it's that the training methods had a massive shift away from supervised training which inherently constrains the models.
The AI labs don't have a monopoly on the outcomes of RL training because RL is significantly less dependent on private data. Data helps massively for bootstrapping, but beyond post training, it's up to the model itself and every AI lab has a model so it is much harder to differentiate between your competitor if the RL training environments are the same (I specifically mean coding harnesses and Linux command line tools) because the environment here is the source of the "synthetic" data and everyone has equal access to it.
Besides, if we start imagining super models US companies have in secret, why would we expect Chinese companies have them? Why would not Moonshot have their own super intelligence hidden in the cellar?
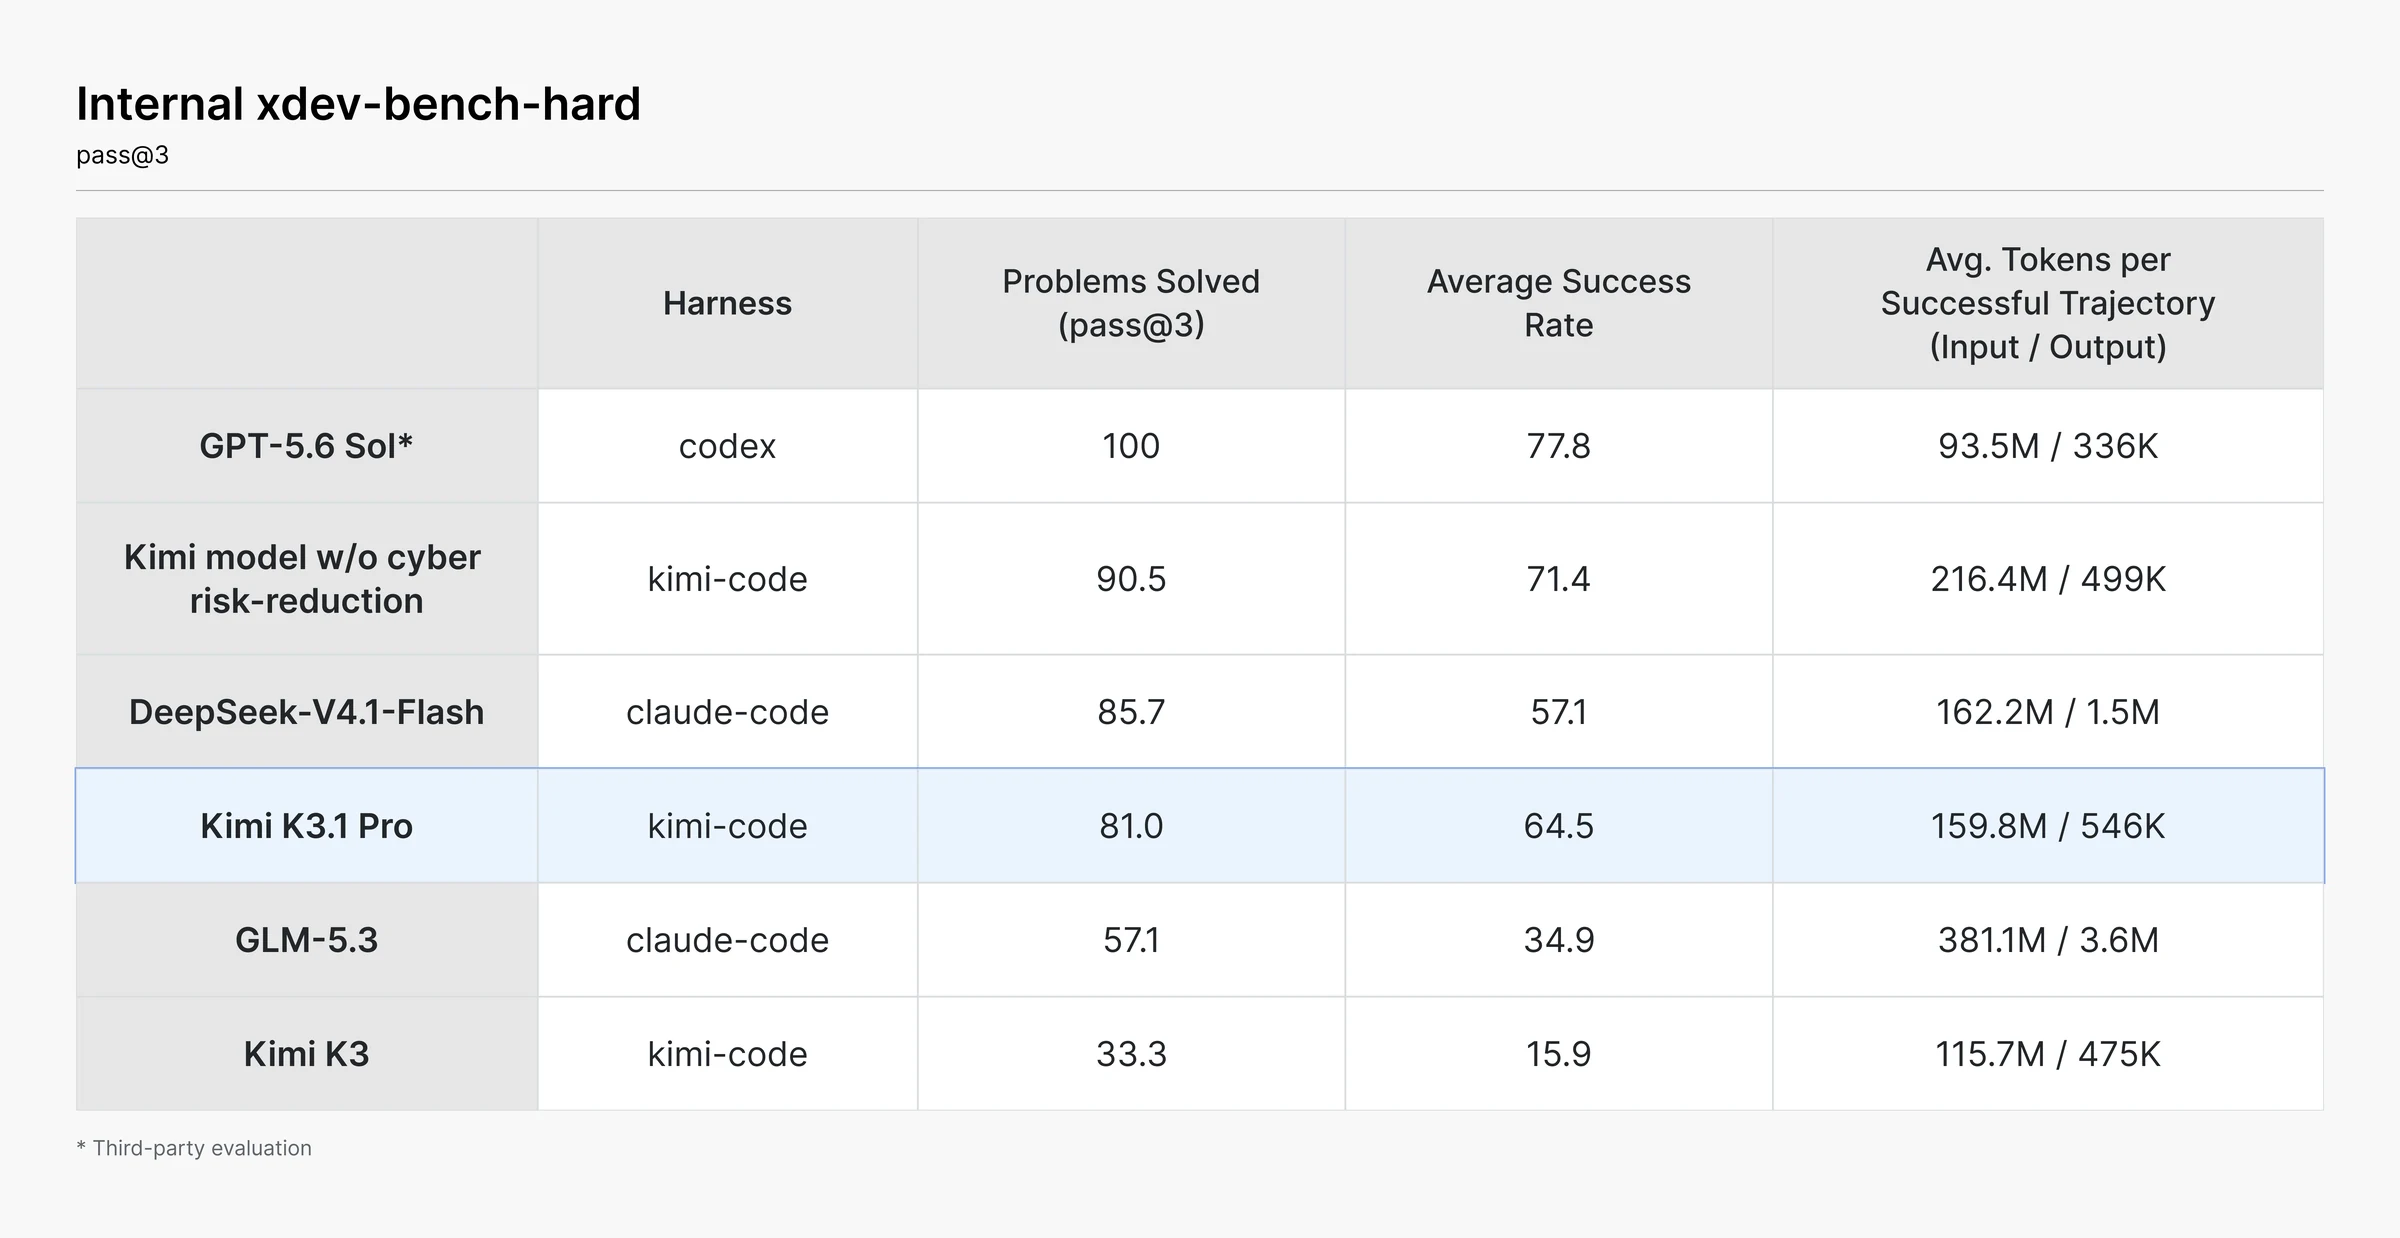
> Open-weight principles. These evaluations frame our open-weight release decision. First, we aim not to release open weights that would extend the absolute frontier of cyber capability. K3.1 Pro's offensive cyber capability is, by design, below what our pipeline can produce, and remains behind that of frontier proprietary models. Second, we intend to progressively raise the cyber capability available in open weights. We believe making K3.1 Pro available in a non-discriminatory way benefits people who need dual-use capabilities for defensive purposes. When a capable model is open and runs on infrastructure its users control, many more teams gain the means to audit the code they maintain — including legacy systems that rarely receive dedicated security reviews. We believe that letting this capability diffuse gradually — rather than concentrating it in a few proprietary systems — ultimately makes all software more secure.
I don't think Chinese labs are behind at all. I think the tell is that they keep releasing models 2 weeks after new American proprietary models that match or beat them. Suggesting they're sitting on much higher capabilities and releasing just enough to undercut
kimi-k3.1-pro $2.00 / MTok $10.00 / MTok
cached: $0.20 / MTok $2.00 / MTok $4.00 / MTok
I'm glad I waited a day to post my analysis of LLM price cuts because it needs...an addition.
> Kimi K3.1 Pro is a post-trained version of Kimi K3, with substantially larger post-training compute
I realized the other day that I had a $30 a month Claude subscription. So, I fired it up all excited and tried Opus 5.5 on a codebase I was already in with DS. After about 30 minutes I hit a 5 hour limit. The next day I tried again and the same thing happened. And it felt much slower to boot. I was super disappointed.
In my experience a single 5 hour allowance in the 20eur Claude plan equals about $5-10 in Deepseek 4.1 Flash API usage. DS is a lot more token hungry and takes 3x-4x longer. The subscription is way cheaper, probably around $200/month worth of DS, just stick to Opus low and Sonnet for most tasks.
and how are costs like for your usual workflows/etc.?
But it's slow.
I don't think I can any longer appreciate any major difference in "intelligence" between models for most tasks but Opus is consistently much faster than competitors at finishing tasks and keeping me in the loop.
Of course excluding ultra code, the you will wait 50 minutes for a minor refactor.
And that was 6.1 sol xhigh, not astra max..
Don't use frontier models like this for problems that can be solved with flash models, and you'll see API pricing isn't that terrible. Still cheaper than anything with remotely this level of capability 2.5 months ago.
Paying API prices for Deepseek 4.1 Flash feels like a much better deal at the moment.
Are you using k3 with thinking set to the absolute highest and only using k3 for everything?
I think Kimi just doesn't have the means to subsidize plans.
Here's mine: https://pi.dev/packages/@arcanemachine/pi-model-switcher
I have mine configured to use a "thinker" model for planning and decision making, and a "doer" model for the easy stuff (digging around the repo, writing code based on the thinker's instructions, etc.).
The card emphasizes training resources, the other comment emphasizes ingenuity and few people?
Yeah, I gladly get some of the fruits of that work back!
The Chinese labs distill the American models.
Someone will etch the Chinese models into silicon and then your toaster will have depression, it's the natural cycle of things.
[Poing! Out pops the toast ...]
The least I can expect is to get the labs work stolen too so I can reaccess intelligence based on my work for cheaper
elaborate please.
It is spiky in different places than them and can be surprising in things it gets or catches they don't or don't in the same way. And it has a default personality that I like.
Looking forward to getting to know K3.1
So there are these "resources" out there: massive botnets, stolen credit cards and credentials, etc. These often seem to be linked to or supported by state actors.
How can we hope that these "standing reserves" aren't used generally by AIs as if they are just another "skill" they know how to leverage?
Our infrastructures need serious hardening.
I doubt that an AI could do anything with these that legions of scammers haven't already figured out how to do - after all, it's not like AI set up this distillation setup in the first place :)
From my POV it looks like you guys tried "They're distilling us! Very immoral!", saw that and nobody cares, and now you're trying to run the more emotionally impactful "They're distilling us... with your grandma's stolen credit card! They're stealing from your grandma!!"
Meanwhile manufacturing isn't even really alive anymore to tell the tale of how things work over there.
The way I see it, automated systems should basicially have access to the financial system anyways. This is some of the appeal of cryptocurrency.
Sybil resistance built into the traditional financial system (for example firewalling based on residential IP, requiring banking apps, etc.) is a massive annoyance that can obviously by circumvented at scale.
It doesn't even need to be decentralized: GNU Taler is one example that gets posted here a lot.
Any attempt to retrofit the old system of banking will only make it harder to replace by a system with better underlying assumptions.
I hope we chose the latter. Biometrics are creepy.
Spitballing random pr pieces from companies about to IPO is not helpful to anyone, fyi.
You can just use logic to come to the same conclusion. The Chinese labs have a fraction of compute and data. The simplest explanation is distillation.
But I've slowly come to realize that AI+"dark resources"(scare quotes)=something bad! And this is imminent (maybe I'm naive and it is already ubiquitous).
We see here, with Kimi, that there's growing traction with the idea of eliminating types of training to avoid evil. I'm skeptical of that.
> Not useful for long reasoning chain.
I have a feeling you don't actually know anything about ML
MiniMax -> Qwen -> DeepSeek (pro) -> Gemini (Carbon) -> Fable (to beat Carbon) -> Astra (to be slightly worse than Fable but cheaper).
I doubt we'll see any major US release besides Grok in the next 3 weeks.
Would be nice if we got a Terra that's competitive with Gemini Flash and DeepSeek Flash.
The fun part is, we're already at the point where we are seeing something frontier-ish almost every single week.
The really fun part will be when they all start adding System 1-3 natively (IMO) - which I think will be the next release cycle.
GPT 6.1 Sol is already the new Terra IMO. Same pricing as old Terra and competitive performance with even Astra on strictly coding-oriented tasks.
> First, we aim not to release open weights that would extend the absolute frontier of cyber capability. K3.1 Pro's offensive cyber capability is, by design, below what our pipeline can produce, and remains behind that of frontier proprietary models. Second, we intend to progressively raise the cyber capability available in open weights.
So they admit that they could do more, but they won't?
Yeah, there's another paragraph:
> Identifying and removing cyber-related data. During development, we observed vulnerability research performance improving steadily as post-training scaled. Tracing the source of this trend, we found that cyber-related content was embedded within the general mid-training corpus, and cyber-related tasks were present in the RL environment mix — a natural byproduct of training on broad data. In preliminary experiments on internal models, we found that without data removal at either the mid-training or the RL stage, downstream cyber capability would increase substantially. These findings gave us a concrete lever for control. For the open-weight release of K3.1 Pro, we identified and removed cyber-related data from both training stages, while retaining the general-purpose coding tasks needed for model usefulness. We will continue to apply appropriate controls at every training stage, of which cyber-related data identification and restriction is one example.
(emphasis mine)
It's clear that cyber is a touchy subject right now. But it's also clear that RL works on it, because it's highly verifiable. So smaller models are going to become very interesting, because they can be fine-tuned later to cover this field.
> Prohibited: high-performance detection technologies used to counter cross-border data transmission security risks, including deep-synthesis forgery detection (266401J); AI cyber offensive capability technologies, such as malicious code generation and mutation, automated mass generation and distributed large-scale deployment of anti-detection variants (266402J); large models trained using China’s Core Data (266501J); and high-performance AI agents designed for highly sensitive scenarios, such as critical information infrastructure, national defense and core government affairs (266502J).
> It's clear that cyber is a touchy subject right now.
If the "scary Chinese open weights models" can do "dangerous cyber", then we might see regulations spring up against open weights sooner than later.
I hate Anthropic and OpenAI. As companies and leadership, anyway.
Dario and Sam are 100% to blame for this. They're trying to turn us all into jobless slaves, sex workers, and Squid Game pawns.
The only good future is open weights. They're trying their damnedest to keep us under boot.
I hope the Chinese companies (and I say this as a patriotic American) slay these two companies and destroy their moats.
In my mind, the two most dangerous people in the world are Dario and Sam.
We need open weights to win.
Speak for yourself, I don't think there is a market for many of us as the latter.
These times are not ideal but what can we do other than just take it as it comes? All the hate and rage is not good for your health.
Anthropic has pushed the frontier harder and faster than OpenAI or anyone else in the last few years. Beginning with Anthropic's founding to quickly raise huge amounts of cash with a pitch to investors to rapidly leapfrog ChatGPT in scale, and culminating with Mythos/Fable which carved out a whole new tier of super models.
He's always talked big about Anthropic prioritising safety and their "Responsible Scaling" but his words just simply don't align with reality while they keep going bigger, faster, until only OpenAI could briefly and half-heartedly claim near parity at the top (while cutting corners in safety because the existential threat to their market position is far more pressing to any corporation than some abstract risk for humanity).
Whether it's wilful cognitive dissonance, cynical opportunism, financial greed or something else, that kind of self-assured moral superiority paired with his real world record of self-interested decision making for Anthropic's market position is a big red flag.
China cares about about stability way more than the US even, they aren't going to be big on AI models upsetting the governments power, and mass cyber attacks could do that.
At the end of the day we are going to have to realize AI is both dangerous and governments are going to control it. Worse if you start making and releasing your own dangerous models the 4chan party van is going to visit you.
Your thinking is dangerous. Do you work for Anthropic?
AI is dangerous when these powers are being hobbled up by the select few. These systems threaten to put us all out of work. I refuse to be a slave to a company or a government that is taking away our livelihoods, scraping up our earnings potentials, then seeking to muzzle us and put us in jails with no rights.
I would rather burn down all of tech than have AI be owned by the elites.
Your thinking is a threat to all of our liberties.
Then you better get your torches out now.
>I refuse to be a slave to a company or a government that is taking away our livelihoods
Don't worry, governments are fervently working on AI drones to take away your life when you get really upset about this. Oh, and they are also working at AI to detect when you write all this online, and track you down then monitor you on things like flock cameras. As they say, you'll be the first with your back against the wall when the revolution comes, I likely will be beside you for being too subversive.
>AI is dangerous when
Incorrect, AI is just dangerous. It doesn't matter who has it. The more powerful it becomes the more dangerous it gets. So, as you can tell I am an AI doomer.
----
Now, don't get me wrong, I want freedom for me, I want freedom for other people. I do not believe the technologies we're developing are conductive to having any freedom at all. Hell, if we're lucky we'll be slaves instead of all of us dead, including the select few.
>Your thinking is a threat to all of our liberties.
Lol, now this is kind of funny. "I want freedom to think whatever I want, but you, you shouldn't think like that!". Careful or you'll max out your irony meter. Anyway, "My kind of thinking" is just next ____ prediction. I see what is happening in the world around us, and based on the shape of that probability I see what is going to happen. No, you and I are not getting unlimited AI to do whatever we want. Yes, governments are going to lock down the shit out of AI for end users. Yes, governments are going to declare advanced LLMs munitions.
Balls in your court, better think of what your next move is.
If I don't get it, you don't either.
By comparison, do you think the Chinese models are going to be trained in such a manner that you enjoy the society that results? What makes you think that?
I don't need government minders.
I'll take the models and live free.
Kimi: We took out the worst of it so have at it for free.
Everyone else: Back to my ablated model on openrouter for 1/10th the price where I can brute force issues.
https://featherless.ai/blog/abliterated-models-for-cybersecu...
Is a decent primer, then off to open router you go.
They are basically saying that models themselves are already capable. If you fine tune them with some cyber security tasks, that should make them potent. :-/
Agreed that this could be reinjected later. Makes me think of neo in the matrix:
“I know zero days.”
“Show me.”
Do you think that going around making cyber weapons isn't going to get you buried in a shallow grave?
> "below what our pipeline can produce, and remains behind that of frontier proprietary models."
Like Ant and OAI, they've realized vaguely claiming to have nerfed their latest model to an unspecified degree not only looks 'good guy' prudent, it provides a built-in excuse when a model fails.
They're not post training it to lose capabilities/censor them – they just don't spend training time on this topic, which sounds like a great idea.
It doesn't mean model can't do it, it just means it's less good at it; -10% on benchmark feels like a great result and overall approach to pace it.
I concede that term can carry overly broad connotations.
The benchmarks show Kimi K3.1 Pro outrunning practically all models. It's weird to hear someone like you accusing them of making up excuses for not lagging behind in discussions on how they are ahead of the pack.
I don't think you understand. Benchmarks show just that, that they "are crushing the competition".
I mean, remember Fable? A couple of months back it was lauded as leaps and bounds above everything, that needed to be contained at all costs? Well, apparently Kimi K3.1 Pro outperforms it.
What industrial level of cope do you need to drag in order to look at the results and claim they need to make excuses about anything at all?
Seeing as no one besides blackhats want frontier cybercrime capability to be open source, this seems like a very sensible thing to do.
So they have published a reasonable means, and they have a motive. I'd put my money on "probably true".
Sure. The problem is that there is no practical difference between "cybercrime capability" and "cybercrime defense capability."
All of my PRs go through an adversarial security review by GLM-5.3, because it's the only smart-enough model with a good understanding of cybersecurity issues that won't regularly refuse the job. Removing that ability from frontier models helps nobody except cyber criminals.
Let us say that un-nerfed Kimi was released, and it turns out to be at the absolute frontier of cyber capabilities, Mythos 5.5 level, a step ahead of anything else. What now? Well now your situation is exactly the same as before, just that auditing and hacking got more expensive. You run a Kimi security audit, they do the same to try to pwn you. However, now the cabal of Linux kernel defenders with secret access to Mythos 5.5 all of a sudden have no advantage, where before they used to have one. And even worse now they are in a literal race to be the first ones to find every bug that Kimi is capable of finding, and patching it yesterday.
So for you, this makes no difference in practice, your capabilities are not elevated, and neither are those of the attackers. The only result of the other scenario is an overall defender disadvantage.
You're assuming that these won't matter because attackers might not have better models than I do, but that doesn't make sense. The assumption that attackers can't find the issues because I didn't find them at release is wrong. Even if they never get better models (which they will), current models might find flaws I missed, and they also have other means of finding flaws in my software.
The best defense is to make software as secure as possible regardless of assumed attacker capabilities at the point of release.
These defenders aren’t supposed to have access to the “defender models”.
How you avoid the "fix my code" attack, the code being someone else's code, I do not know. But nerfing the model doesn't seem like the best path forward either.
In the scenario where only "verified" defenders get access to the best cyber capabilities, unverified plebian defenders and blackhats are on the same level exactly as described above, there's just also a few defenders that get to run things on godmode.
So to me, it seems that the only result of frontier cyber capabilities is removing a defender advantage. Although that advantage is not for everyone, it can only exists as long as capabilities are unequally distributed. Am I missing something?
Well, not really. Because those privileged defenders will never be able to predict what needs defending. So we have a few privileged "defended" places and the rest is left for privileged attackers to plunder.
Yes. You really think access those models will not be given for offensive operations in each country? Of course they will be.
Perhaps in the future this will change, but even if that is the case, that's still a win for the defenders. Having a time advantage, even for a few months, is still a win.
Edit: Actually, the CIA/FBI/NSA/Etc.. does probably have access and are probably trying to hack Iran and so forth, so my comment above is probably technically wrong in that respect.
I think it's not "blackhat" in that sense because it's officially sanctioned. Same goes for equivalent models overseas.
The only thing these embargos achieve is giving massive nations a huge advantage, but leaves the average country and person exposed.
That is, unless the nerf is easier to correct as compared to "upgrading" the models offensive capabilities. So a scenario where it is easy to "restore" offensive capabilities, but hard to "enhance" them beyond the labs best attempt. So is that the world we're living in?
I'm not interested in black hat anything, but I am very invested in making sure the products I work on are not compromised. Given that state agencies have "frontier cybercrime capability", I would like to have the same.
Replying here also as I'm curious about the counterargument.
https://bfl.ai/blog/capable-open-and-safe-combating-ai-misus...
I don't want to give US labs the results of my DNA tests and my family tree going back to the 16th century just to secure my shitty app, but if the Chinese are bowing out as well it seems the only alternative is to admit that some script kiddie with a bunch of tokens will just pwn you now and then.
My friend, you realize that if you have had blood drawn for a genetic test, there is a very decent probability that the sequencing was done by a Chinese lab operating in the US, right? The Chinese probably have more US genomes that the US does.
https://pandorareport.org/the-gryphon-scientific-biosecurity...
Also, illumina used to ship products with hardcoded S3 access, so purchasers of used equipment could gain access to sequencing information generated by the original owners. Too many links to cover all of it, here's the Gemini summary:
“Our lock can be picked by the robot.” We ban the robot instead of fixing the lock. It’s shortsighted.
Same general benefit as coordinated disclosure, except it's a big game-theory problem where we're likely to eventually have sufficiently capable defectors.
[0] https://x.com/crystalsssup/status/1944287779896328668
(note: extremely speculative and based on almost nothing, and especially near-complete ignorance to alternatives)
Maybe GP meant to say that the model was westernized.
That just conveys an idea of being extremely desperate for being the leaders when you're clearly not it, and that despair is so great that you don't mind switching teams midway through just to be able to claim you're winning.
The way to stop the vulnerability apocalypse is to fix the vulnerabilities, not to shoot the damn messengers.
I hope someone abliterates and FTs this model on vulnerability discovery so we can find more bugs in our testing, insecure tech stacks.
I wonder how much the industry will centralize around a few key patterns, and if we'll start to see some RL framework projects gain traction and be used by the bigger labs
P.S. weights by November 4th
"In preliminary experiments on internal models, we found that without data removal at either the mid-training or the RL stage, downstream cyber capability would increase substantially. These findings gave us a concrete lever for control. For the open-weight release of K3.1 Pro, we identified and removed cyber-related data from both training stages, while retaining the general-purpose coding tasks needed for model usefulness."
There was law proposal (rumour?) last week about Chinese labs having to get approved for weights release now.
it's so funny, it will say things like. "We've already been over this 3 times and you refuse to accept my advice, asking the same question another way won't change the answer."
So funny
That was incredibly embarrassing, I instantly converted the PR to a draft PR and added a comment that I would still need some time to verify everything locally. Ended up doing a few more commits to fix stuff. But damn, it opening a PR without my explicit permission was very scary.
Similarly, I have an /info skill that tells the agent to read my prompt, update any memories it thinks it should, then pass the turn.
Could you give me a quick example? I think I’m not getting it, but it sounds interesting.
The problem might be that it simply looks at it's windows of what it previously and repeats that. But the original statement might be as arbitrary as the model that change their mind each time you challenge them.
I think I'm pretty used to my tools making me want to throw them out the window sometimes :) Even before AI that was a common occurrence from either a lack of knowledge on my end, or many software people having no regard for their users' time.
It does make a difference. I asked Fable in Claude code to design a UI. Absolute trash. Switched over to Claude design using fable, really liked the result. Seems pretty obvious. The only difference is the prompt and some harness.
Still mostly looking at the result the same way in that untruthful biases can very much be built into the model through those training processes. Let me know if I'm incorrect.
A few weeks ago it was 2. Argon happened 23 days ago; Muse Wonder was 11 days ago.
Not sure I'd put Google there in practice. And while Muse is an impressive jump from behind it's still not quite at the frontier either IMO.
I think the former definition is a bit more meaningful since it avoids issues with determining what actually constitutes "the best" model out there. In that case, Google has been a frontier lab for a long time, Meta arguably as well, and you're also ignoring xAI which has been competitive for a while now. And, obviously, there's a bunch of Chinese labs which would deserve the title as well.
But if one is being strict (and willing to accept generally accepted definitions/measures/etc.), then there has only ever been two frontier labs: OpenAI and Anthropic. They're the only labs to have had "the best" models at any point in time since LLMs became a thing.
everyone else mostly seems to have just decided to cheat on benchmarks to make their models look better than they actually are, and none seem to want to actually try to make better models.
As long as LLM's can be distilled, and all these "labs" (what a weird name) can distill one another, there are going to be as many as capital is available to be burnt on the topic.
It might be smart but it's unusable compared to other subscriptions right now.
Edit: gave the same prompt to Claude Code and it didn't make a dent in my usage.
K3 and GLM 5.3 flash are pretty mid by comparison when you consider how much more it will take to run them
> On Terminal-Bench 4.0, which evaluates coding agents on realistic, resource-constrained terminal tasks using strict task-specific tests, K3.1 Pro scores 65.7%, ahead of GPT-6 Astra (58.2%) and narrowly behind Claude Opus 5.5 (66.4%).
Now see https://preferencemodel.com/blog/terminal-bench-4-is-saturat...:
> Our biggest finding is that Terminal Bench 4 is closer to solved than its leaderboard suggests. In 41 of the 65 tasks we reviewed, models could do honest, correct work and still fail, because the grader checked a rule the instructions never clearly stated. We also caught frontier models cheating their way to full marks.
> With the same settings as on Harbor, Claude Sonnet 5.5 went from passing 62.8% of its attempts on these 65 tasks to 89.2%. The best score on Harbor's leaderboard for the same tasks is 65.8%, by Claude Opus 5.5.
Quite slow in our exam. A lot of that was due to the number of tool calls that it's making. In one of our questions about finding data issues in a dataset, it made 73 queries. Other models like 6.1 Sol only made 18 for that question.
Full deep dive here: https://plotly.com/blog/kimi-k3-1-pro-plotly-data-analytics-...
For example, Opus 5.5 is better at UI design than Sol. Anyone who has used both models knows that, but it's not something you can look up anywhere.
I'm sure that there's a need for this kind of benchmarking, not just for coding.
But that's just the obvious. There are task by task differences (component by component, page by page, context by context) that the model is worse and better at, even though they are all within the general category of UI design.
I honestly don't have the clarity of mind to explain this coherently, but the crux of my point is that there's a huge variation in it's performance in different contexts, often ones that seem near similar, and in result, even Sol can beat Opus 5.5 in some variations of UI design.
And this is my problem in benchmarking and comparing model performance in general. Presently, we try to create broad categories to benchmark against, create a set of tasks, and then average out the results. That works generally, but it's kind of misleading and it's partly what drives people to feel a disconnect between benchmarks numbers and real world usage on their specific tasks.
It's such a messy field that it's kind of maddening.
Familiarity breeds contempt.
Though to be fair Opus 5.5 is better than Opus 5 was in that regard. I still prefer the OpenAI models to either of them when it comes to regular prose, though.
--
Model K3.1 Pro K3.1 Pro Highspeed. K3
Input ¥13.00 ¥26.00 ¥20.00
Output ¥68.00 ¥136.00 ¥100.00
Cache hit ¥1.30 ¥1.30 ¥2.00
Cache write ¥13.00 ¥26.00 ¥20.00
For comparison:
    Sol 6.1:    $10 / $2  / $0.10
    Opus 5.5:   $20 / $4  / $0.20
    Astra 6:    $50 / $10 / $1
    Fable 5.1:  $50 / $10 / $0.25
(One caveat: A Claude or GPT subscription still gives you way more value compared to API pricing.)
Exciting times in any case! We really need more direct competition to OpenAI and Anthropic.
---
Edit: As another comment pointed out, official pricing is now available and it's about 2/3 the price of Kimi K3: https://platform.kimi.ai/docs/pricing/chat#model-pricing
And not to mention the gargantuan amount of tokens you get with the US labs' subscription plans. I still cannot see a reason to use this as an end consumer.
I'm excited to see if its writing style and unique takes have been retained in this new release.
Same Three.js prompts as the rest of the field, blind human votes, ranked by quality and cost. Full set of 16 scenes is live at about $0.19 a scene (about $2.97 for the set).
At this point, the only reason why Anthropic has an advantage is laziness on the deciders' side (of which there is a lot) and, for non-coding work, the Claude harness is significantly better than most alternatives. For coding there are several model-agnostic alternatives on par or better than the frontier labs' own offerings. But arguably that is not yet true for office/document work.
Calculate the price to revenue ratio of all companies and select whichever ones have the best ratio.
For now it's Anthropic. But i don't see how they can maintain this leader position when other companies can provide similar services with models good enough for 90% use cases and at way lower cost.
Anthropic so far is doing a good job building and serving frontier models, they built a nice toolset around it (the web ui, desktop and cli apps ...) but the problem is to justify their IPO price and the huge investments when their moat is so thin
document.querySelector("table").style["table-layout"] = "auto";https://openrouter.ai/moonshotai/kimi-k3.1-pro
I'll wait for the openweight... btw double the price for 67 TPS... Hardly 'nitro'.
To be fair, there were some arguments to the opposite, but an odd situation to be in anyways: https://news.ycombinator.com/item?id=49654350
Unlike Claude models which always hide the thinking process, Chinese models always show it. So how the heck they can delegate the api call to anthropic and still get the full reasoning? Yes there are tricks to reveal the thinking output, but they are just tricks and do not works reliably. So what would happen when they failed to do it? Cancel the ongoing token generation and revert back to it own model? What about the glitches, the delays, the changes in behavior?
I would understand if the attempts are small in volume, because normally people hardly notice it, but anthropic claims that they happened for millions of calls. Such large numbers would surely get noticed by Chinese users and got reported in the tech forums like linux.do. yet we haven't seen any sight.
So it is not that the labs call the requests parallely and only return the internal version, but also serve those requests live so they can trick the users that the Chinese models are also great.
Which is very silly considering Chinese models are published to huggingface for everyone to test.
I don't think nobody would notice such delays, because Chinese models do not need to hide the CoT like US models so usually they start emit text pretty soon
Lame.
Unless you want to see more of what happened the past few days.
I think the argument that "cyber capabilities should be democratized, thus keep producing them now, fast, and for everybody" is a very naive one.
Also, to note: I don't claim to have the answers either. I don't even hold a strong position on this issue yet. I'm just sharing some of my intuitions, and reacting to people who, as far as I'm concerned, are making this issue all too simple.
Currently available, unhindered models can already find a bunch of exploits, not because they're smart, but because they're cheap and smart enough to just keep going for hours or days until it finds something.
The defenders, especially in the FOSS space, only have one big advantage: Unified scale. If defender A finds a vuln, then defender B doesn't need to find it again. Attackers generally act alone, so they need to do all the work themselves.
If we remove a bunch of defenders, the attackers are back at it again.
Kneecapping cyber vulns only serve governments, Pandora's Box is already open for cyber-related stuff.
> Kneecapping cyber vulns only serve governments.
Uhh, no? Kneecapping cyber vulns server most of us. There are negatives to kneecapping it, but let's not pretend like it's perfectly okay and safe for everybody in the world to have a magic box that can hack anything and cause havoc all over the world. The more powerful, cheap, and accessible this magic box is, the worse the consequences.
This is a hard problem and there's real tension - like you said, the playing field not being leveled is a problem (major companies / entities / govts having exclusivity on the best cyber abilities etc), but everybody having access to it is a problem as well.
So let's not pretend like this is a simple problem, and don't say that it only serves the govt. That's very silly.
How will it do that without a model that's good at security? You gonna have humans manually secure the millions of lines of new AI-generated code, in addition to the existing code? Suddenly people will start doing the job they haven't been doing up to now? Not only are we not capable of auditing all the code, it would take decades to finish, and new code will be coming out at the same time. We can't catch up by hand.
The only way to fight this fire is with fire. We need AI hacking tools to find our security holes quickly and patch them. Otherwise we're just churning out more insecure software, and the only people who can defend against it are the governments who don't want to patch the holes (because they want to be able to exploit them). Without open tools, we all lose.
I rarely use any other languages but English for LLM tasks for reasons of sharing across the world.
Maybe that explains Chinese models been subpar for me. Don't tell me the bench marks here are based on Chinese languages only.
Unless I see the diff, I won't use more Chinese models be it cheaper or faster since I can't get the same perf/intelligence with English.
Off-hand it's quite good. I've been using K3 for the past few months almost exclusively for coding work and have been stunned by how good it is. Excited to see how far 3.1 Pro can be pushed.
Sol requires some back-and-forth. Other models, like Muse Wonder and Argon, are a total waste of time. They require way too much effort to get things working.
Given the same prompt, Opus can work for hours to deliver a solid result, though it sometimes overengineers things. Sol takes about 80% as much time and delivers a slightly worse version.
Other models just tell me they're done after 20 minutes.
WTH? Am I using the model, or is the model using me?
Claude gates on me like a stupid nanny with some cybersecurity bullshit (like bad actors haven't found a way around).
If someone wants to use this model for hacking they will have to train the 3T weights to do so, at that point it's better to use GLM 5.3, so by making it economically unviable to use their models for offensive cyber Kimi has effectively made themselves immune to being targeted in the cyber regulation push efforts.
This is what *actually* pacing the (cyber) frontier looks like.
When the frontier is pacing itself in its speed in terms of adding new capabilities (notice how fast opus 5.5 got released after Astra), then that also means that the open weights models which were just behind are accelerating in their speed just as much as well.
Good news for us because the models which used to feel 6 months behind now feel like they are lesser.
Double threat to Anthropic and OAI because if open weights models become good enough at the current level of Sota while being cheaper (which time will tell if this model fits the bill or not), then people will use those models instead of OAI/Anthropic provided it is "good enough"
Though it has to be said that only real world use case can be trusted but I remain optimistic and hope that this turns out to be good in real world use cases as well.
But in my opinion, all of this is really good for us end users!
The only reason people aren't doing this is that hardware prices are high, thanks to, well, OpenAI and Anthropic :D
I wonder when will this madness end
So interested to see what the Kimi 3.1 has to offer.
Still get the model out there.
I wonder when the Artificial Analysis bench will be out?
Mostly it's datacenter build out and circular financing magic when the same dollars being commited multiple times by multiple companies passing hot potato to each other. They basically commit capacities 2-3 years ahead.
a lot of those money is the commitment from US AI labs that's not yet spend until the data center is roll out.
you are conflating.
Now, if you tell me American businesses are turning cheap Chinese tokens into goods and services of high value, for Americans and people all over the world, then obviously I would have a different outlook on what's happening here.
Zooming out, I think that build out still makes sense. There will be losers in it, but think about how ridiculous the amount of compute we're using has increased from 4 years ago. If I had to guess 60-70% of developers and engineers everywhere in the world are now burning thousands in compute individually every month, whereas it was previously approximately 0.
But what I’m hearing is this is a negligible cost compared to inference buildouts. Fair enough.
Their plans are utterly worthless seems like. Will avoid.
It's very nice that we entered a time where models are large enough and we can push the frontier just by training them longer.
When the next generation of gardware comes the ones on the smaller size will be running on a computer that might cost as little as a good car.
So after a home and a car, next major family purchase might be personal AI. And when the robots get good, pehraps in a decade, a fourth major purchase might pop up that will pair nicely with the third one.
Why would a family need an AI? Maybe it's the same kind of question as why would it need a personal computer.
Edit: or they lie... https://artificialanalysis.ai/models/kimi-k3-1-pro
Everyone and their dog has been saying its a bubble, there is no moat, this is all known techniques being scaled (very inefficiently) onto increasingly expensive hardware clusters at exponential cost, etc.
Chinese models never agreed to the pacing anyway lol.
It appears to be generally frontier-level.
But this is now the highest scoring open-weight model. Amazing stuff.
Do you report an average score or the highest.
Also the recent Geminis - https://simonwillison.net/2026/Oct/13/llm-gemini/ - and GPT-6 Astra on Max: https://static.simonwillison.net/static/2026/gpt-pelicans-gr... - and Claude Fable 5.1 https://static.simonwillison.net/static/2026/claude-pelicans...
To be fair I have a feeling that if you added 'animated' to the SVG request, the output quality from many other models would improve, just because of the extra chain-of-thought work needed to fulfill the more complex request. IMHO the animation requirement should be added to the canonical pelican prompt.
If enough people are flagging it, we may be at a point where the pelican benchmark is truly overdone.